Trace Your Salesforce Data, From Field to Dashboard
A native connector, now in public beta, that maps Salesforce data lineage from objects and fields to the reports and dashboards your leaders rely on.
Kindly fill up the following to try out our sandbox experience. We will get back to you at the earliest.
Provide clarity on data origin, transformations, and usage across your landscape.


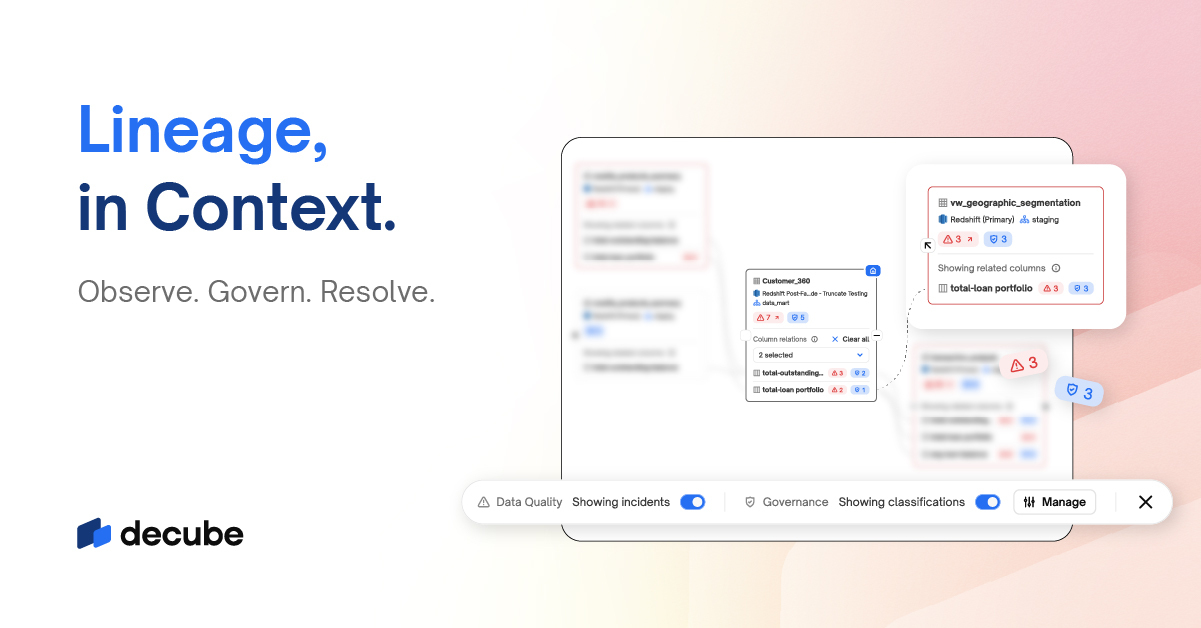
Our Column-Level Lineage mapping offers deep visibility into your data pipelines, enabling you to trace issues down to the most granular level. By pinpointing the exact origin of data discrepancies and understanding their downstream impact, you can resolve problems faster and more effectively. This level of insight ensures timely resolution and minimizes disruptions across your data workflows.
Easily define and manage data lineages manually wherever automated tracking may fall short. With Decube, you can establish an approval workflow for data owners, ensuring that every manually defined lineage is accurate and aligned with organizational data governance standards. This flexible approach helps maintain data integrity and fills in gaps for complex or custom data assets.
When changes occur within a data asset—such as a table, job, or dashboard—the owners of these affected components can easily notify downstream stakeholders. This proactive communication helps downstream asset owners understand the potential ripple effects of the changes, enabling them to take necessary actions to mitigate any disruptions or data quality issues.
Engineers now have the flexibility to update data lineage directly through APIs, bypassing the need for manual updates via the user interface. This streamlined approach saves time and enables seamless integration with existing workflows, allowing for faster and more efficient management of data lineage.


Detect issues in freshness, volume, schema, and quality before they reach your dashboards.
See how data flows field by field, mapped automatically from your SQL.
Trace data across warehouses, BI, and pipelines in one connected graph.
Find the source of a broken metric and see everything it affects.
Lineage is built automatically by parsing your queries and models.
Push and pull lineage programmatically and stay open-standard.
Push and pull lineage programmatically and stay open-standard.

Decube connects to your warehouses, lakes, BI, and pipelines in minutes.

Decube parses your SQL and models to build column-level lineage automatically.

Trace any field to its source and see downstream impact before you change it.
Most tools stop at the table. Decube traces every column, so impact analysis is precise.
Continuously monitor freshness, volume, schema, and pipelines, and get alerted the moment something breaks.
Shows exactly which field flows into which, so you see the precise impact of any change.
Decube maps automated column-level lineage, so you fix the right thing the first time.


Auto-map lineage across your warehouses, lakes, BI, and orchestration tools, with OpenLineage and API support. And many more..
Amet minim mollit non deserunt ullamco est sit aliqua dolor do amet sint. Velit officia conseq uat duis enim velit mollit.
Decube runs on a metadata-only architecture and meets the standards regulated teams require.

Safeguarding your information with industry-leading standards.

Ensuring your information is protected with the highest level of integrity.

Ensuring the confidentiality and integrity of your healthcare data.

Protecting personal data with robust privacy and security measures.

Your data is encrypted in motion with TLS and at rest with AES-256.
If any of these sound familiar, your data needs monitoring you can trust.
A dashboard breaks and no one knows which pipeline caused it.
Schema changes break downstream reports without warning.
Auditors ask where a number came from and you cannot show it.
Analysts do not trust data because they cannot trace its origin.
Impact analysis before a change is manual and error prone.
Tribal knowledge is the only map of how data flows.
Built for teams that must trace, trust, and prove where their data comes from, and see what breaks downstream before they change anything.


Trace critical data elements to their source for regulatory reporting and audits.

Column level lineage from source to report
Data origin evidence for BCBS 239 and audit
Downstream impact analysis before any change
Root cause tracing when numbers look wrong

Prove how actuarial and risk numbers were calculated, field by field.
End to end lineage across claims pipelines
Trace how premiums and reserves are calculated
Impact analysis before model or rule changes
A clear audit trail for regulators

Untangle how data flows across many systems and pipelines.
Lineage across multi cloud and legacy systems
Column level tracing for billing accuracy
Downstream impact before pipeline changes
Faster root cause on data incidents

Understand impact before changes across a large, complex data stack.
End to end, column level lineage at scale
See every downstream report before you change a field
Trace any metric back to its source
Shared context across analytics and AI teams
Trusted by organizations operating under OJK, BNM, MAS, and APRA regulatory frameworks across APAC.
Amet minim mollit non deserunt ullamco est sit aliqua dolor do amet sint. Velit officia conseq uat duis enim velit mollit.
Rated 4.6/5 on


Automation of Monitors
Data Lineage
Their data contract module is amazing which virtualises and runs monitors.
Big fan of their UI/UX, it simple but managing all the complex task.
My team uses on a daily basis.
Seamless integration with all the data connectors. We also liked the new dbt-core connector directly integrated with Object storage.
Automated Column-Level lineage
Perfect blend of Data Catalog and Data Observability modules.
Business users are able to understand if the reports /dashboard have issues / incidents.
Personally liked the monitors by segment since we have mulitple business it provides incidents breakdown by attributes.
UX and UI, features, flexibility and excellent customer service. People like Manoj Matharu took the time to understand my business and data needs before trying to solution.
One of the best-designed data products. Our complete data infra is getting observed and governed by decube. My fav is the lineage feature which showcases the complete data flow across the components.

What I appreciate most about Decube is its intuitive design and the way it supports maintaining data trust. The platform allows for straightforward monitoring of data quality, making it easier to detect issues early on.One of the most valuable aspects is the transparency it brings to our data pipelines, which also streamlines collaboration among teams. The greatest benefit is the assurance that our data remains accurate, consistent, and prepared for decision-making, all without the need to spend countless hours troubleshooting.

Decube is packaged of solution for us. We were struggling to find one good tool in which we can intigrated with our existing data stack we are using mysql. As a DevOps we used to write crond jobs to check data quality but when we adapt this tool the work and quality both are improved. I highly recommend !


Data lineage is the map of how data moves and transforms across your stack, from source systems through pipelines to dashboards and models. End-to-end, column-level lineage matters because it lets you trace any field back to its origin, see the downstream impact before you change something, and prove to auditors exactly how a number was produced.
Data lineage gives you faster root-cause analysis when data breaks, impact analysis before you change a table or column, audit and regulatory traceability, safer migrations, and more trust in dashboards and AI. Column-level lineage makes each of these precise, down to the individual field rather than just the table.
Regulations like GDPR, HIPAA, and financial reporting standards require organizations to prove where data comes from, how it is transformed, and who has access. Data lineage provides the visibility needed to demonstrate compliance and reduce risk.
Common challenges include siloed systems, manual documentation, evolving pipelines, and incomplete metadata. Automated lineage tools help overcome these challenges by parsing queries, tracking dependencies, and keeping lineage up to date.
A modern data lineage tool should capture lineage automatically from your warehouses, dbt, and BI tools, resolve it to the column level, show it end to end across every source in one view, and let you run impact analysis. Decube does this across Databricks Unity Catalog and non-Databricks sources together, with no manual mapping.
Yes. Decube consumes Unity Catalog lineage and stitches it together with your production databases, pipelines, and BI into one end-to-end, column-level graph.
Bring lineage, quality, governance, and AI together in one platform—so your teams and AI agents can act with confidence.