Enroll to explore sandbox
Kindly fill up the following to try out our sandbox experience. We will get back to you at the earliest.
Kindly fill up the following to try out our sandbox experience. We will get back to you at the earliest.
Ten data lineage best practices, the coverage and freshness targets to set, what a complete lineage record must contain, and when native lineage is enough.

Updated on
"The goal is to turn data into information, and information into insight." - Carly Fiorina, former CEO of Hewlett-Packard
Knowing where data came from and where it went is the difference between a number a team trusts and a number a team argues about. That record is called data lineage, and it is the part of governance that gets asked for first when a figure is wrong, when a column changes, or when an auditor arrives.
This guide sets out ten data lineage best practices, each with a target you can measure yourself against, and then answers the three questions people ask once they start implementing: how lineage differs from data flow, which tool a financial services firm should choose, and whether the lineage built into a modern warehouse is enough on its own. If you are still working out what lineage is before deciding how to run it, the data lineage concepts guide covers the definitions this page assumes.
Data lineage follows a data asset from where it originated, through every transformation applied to it, to every place it is consumed. It matters because almost every question that stalls a data team is a lineage question wearing a different hat. Why does this figure differ from last month. What breaks if I drop this column. Who is allowed to see this field. Where did this customer record come from.
In a modern stack, lineage is the map of how data moves between systems, how it changes along the way, and who touches it. Rather than a single diagram, it is a graph assembled from metadata: query history, transformation code, orchestration logs and connector metadata, stitched into one view of the path. The reason it belongs to governance rather than to engineering alone is that engineering owns the pipeline while the business owns the meaning of what flows through it.
A working data lineage framework has four moving parts, and a gap in any one of them shows up later as a gap in the graph:
Together those parts give a picture of the journey a data asset takes and how it changed along the way.
Lineage earns its budget in four places, and it is worth being specific about them because "better governance" is not a business case:
"Data lineage is not just about tracking data; it's about understanding the story our data tells and ensuring that story is accurate and valuable."
Data flow is the route data takes through a pipeline while that pipeline is running. Data lineage is the stored historical record of which inputs produced which outputs, kept at table and column level. Data flow is a design and operations view that answers where a job is now and where it is stuck. Lineage is a governance record that answers which report breaks if this column changes and where this value originally came from. The two overlap on the diagram and diverge completely on the question they answer.
The practical consequence is that a good orchestration tool gives you data flow and does not give you lineage. It knows that task B runs after task A. It does not know that column revenue_net in a finance dashboard is derived from three columns in two source systems, or that a business rule was changed by a named person last quarter. That is why lineage is captured from metadata rather than read off a pipeline diagram.
| Question | Data flow | Data lineage |
|---|---|---|
| What it describes | The route data takes through a running pipeline | The recorded relationship between an output and every input that produced it |
| Time frame | Now, or the current run | Historical and current, kept as a record |
| Granularity | System and pipeline | Table and column |
| Where it comes from | Pipeline design and orchestration metadata | Query logs, code parsing, connector metadata and catalog integrations |
| The question it answers | Where is this job stuck and what runs next | Which report breaks if I change this column, and where did this value come from |
| Who owns it | Platform and data engineering | Governance, with engineering supplying the metadata |
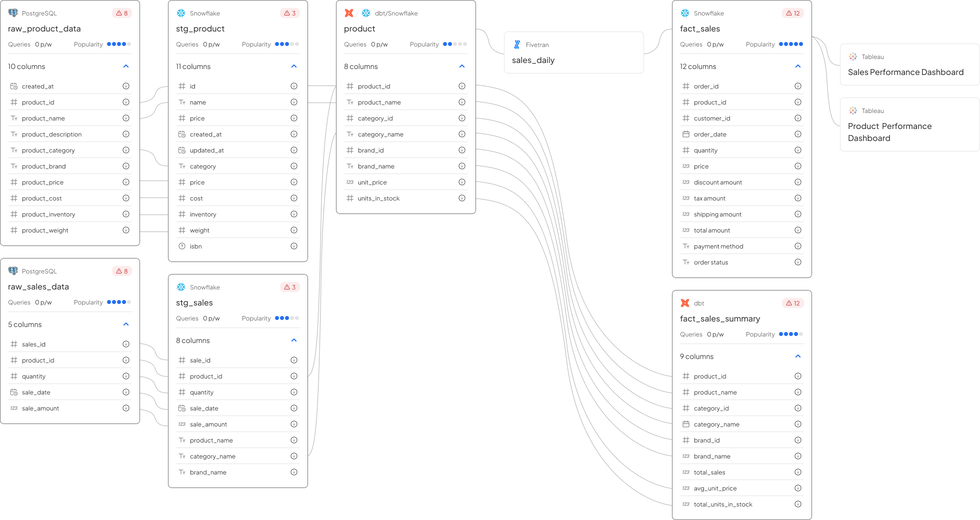
A data lineage framework is the set of elements that have to exist before lineage is reliable enough to govern with. Each element produces something specific, which is the test of whether you actually have it:
| Framework element | Purpose | Benefit |
|---|---|---|
| Metadata management | Organize data asset information | Improved understanding of what each node in the graph means |
| Data flow mapping | Visualize data movement | Identify bottlenecks and optimize processes |
| Impact analysis | Assess changes in data systems | Mitigate risks and plan updates effectively |
| Automated lineage discovery | Capture the graph from metadata rather than by hand | The graph stays current without anyone maintaining it |
| Data quality monitoring | Attach quality checks and results to lineage nodes | A failing check points at the upstream cause instead of the symptom |
Metadata management is the element people underinvest in. Collecting, storing and organizing information about data assets is what lets a person read the graph, because without it every node is a table name. Data flow mapping is the element people overinvest in, because a picture is satisfying to produce and easy to let go stale.
A lineage record is complete when it can answer every question an auditor or an incident review will ask without anyone having to remember anything. That is six requirements, and they are worth writing into your standard as acceptance criteria rather than aspirations.
| Requirement | The question it answers | Minimum granularity |
|---|---|---|
| Source of record | Where did this value originate | Column, named to the source system and field |
| Transformation logic | What was done to it, and in which piece of code | Statement or model level, captured from the code |
| Destination and consumers | Who reads this, and in which report | Report, dashboard and downstream table level |
| Business rule ownership | Who decided this rule, and when | A named owner and a date on every rule |
| Change history | What changed since the last review | Versioned, one entry per change, retained for the audit period |
| Coverage boundary | Which systems are and are not in this graph | An explicit list of systems in scope and out of scope |
The last row is the one most teams skip and the one that costs them credibility. A lineage graph that silently excludes two source systems is worse than no graph, because people trust it. State the boundary on the page where the graph is published.
The ten practices below are ordered the way an implementation actually runs. Standards first, because they are cheap before mapping and expensive after. Capture and integration next. Quality, compliance and tool selection last, because tool selection is a decision you make better once you know your own coverage gap.
Before starting, agree the targets you are working towards. These are the ones we recommend, and the point of writing them down is that they turn "improve our lineage" into something a team can pass or fail:
| Target | What it measures | Recommended threshold |
|---|---|---|
| Object coverage | Share of production tables and views with automated lineage | 90 percent or more |
| Column coverage on regulated data | Share of assets carrying personal, financial or health data with column level lineage | 100 percent, no exceptions |
| Cross system coverage | Whether every ingestion, transformation and consumption tool in the critical report path appears in one graph | Every system in the critical report path |
| Freshness | Time between a pipeline change and the graph reflecting it | Under 24 hours for production, under 1 hour for regulated reporting |
| Ownership | Share of critical nodes with a named technical owner and a business steward | 100 percent of critical data elements |
| Retention | How long historical lineage is kept | At least as long as the longest audit lookback you are subject to |
Data lineage standards are the written rules that make two people document the same pipeline the same way. Set them before mapping begins, because retrofitting a naming convention across a live graph is the kind of work nobody ever gets funded to do.
A usable standard covers five things: the metadata each asset must carry, the naming convention for systems, datasets and columns, the granularity required at each tier of criticality, who signs off on a lineage record, and how often it is reviewed. Publish it as one page with a template attached, so that recording lineage looks like filling in a form rather than writing a document.
The target: a written standard and a template in use by every team producing lineage, reviewed at least annually and after any change to your regulatory scope.
Documentation is where lineage becomes evidence. The protocol should say what has to be recorded, in what form, and with what version control, so that a record written eighteen months ago is still legible today.
| Documentation element | Description | Importance |
|---|---|---|
| Data sources | Origin of data | High |
| Transformations | Changes applied to data | Critical |
| Data destinations | Where data is stored or used | High |
| Business rules | Logic applied to data | Medium |
| Change history | What changed, when, and who approved it | Critical |
Version control is not optional here. The question an auditor asks is rarely what the lineage is today. It is what the lineage was on the date the report they are investigating was produced.
The target: every critical data element documented against all five elements above, held in version control, with the change history retained for the full audit period.
Lineage fails politically more often than it fails technically. It crosses engineering, analytics, risk and the business, and work that belongs to four groups belongs to nobody unless somebody is named.
Bring stakeholders in before the standard is finalised rather than after, so the granularity argument happens once. Run a short regular review where changes to the graph are shown to the people who consume it. Give every critical data element two names against it: a technical owner who can explain how it is produced and a business steward who can explain what it means.
This is also where lineage stops being a lineage project and becomes part of a data governance program, because the ownership model is the same model.
The target: 100 percent of critical data elements carrying a named technical owner and a named business steward, reviewed on a fixed cadence.
Lineage without metadata is a graph of table names. Metadata management is what turns each node into something a person can reason about, and the two systems should be the same system rather than two tools someone reconciles.
Capture metadata automatically from databases, files and applications, and classify it as it arrives. Classification is what makes the regulated subset of your estate visible, and it is the input to the column coverage target above. If a field carrying personal data is not classified, it will not be prioritized for column level lineage, and you will not know that until someone asks.
A central repository holds information on sources, transformations and usage in one place. With one in place a team can track how data changes over time, find relationships between assets, evidence compliance with data rules, and act on quality problems at the source rather than the symptom.
Automated discovery scans the estate and proposes the graph rather than waiting for someone to describe it. This is the difference between a catalog that reflects the estate and one that reflects whatever was true when the last person updated it.
The target: metadata capture running on a schedule against every registered system, with classification applied automatically and reviewed by a human on regulated assets.
Manual lineage decays from the day it is written. Automated capture is the only version that stays true, and the second half of this practice is the half people skip: automated capture still has to be audited, because a connector that silently stops reporting looks exactly like a system with no dependencies.
Discovery tooling parses transformation code and query history to infer relationships that nobody documented, including the ones in stored procedures and ad hoc scripts that no design document ever mentioned. That is where most of the surprise lineage lives.
Continuous tracking updates the graph as changes happen rather than on a nightly rebuild, which is what makes the freshness target above achievable. For regulated reporting, a graph that is a day behind is a graph that cannot be used to answer a question about today.
Modern data lineage tools connect to warehouses, transformation frameworks, orchestration tools and business intelligence platforms, which is what produces a single graph rather than four partial ones. Integration breadth is the capability that decides whether cross system coverage is achievable at all, so check the connector list against your own stack before anything else in an evaluation.
| Capability | Benefit |
|---|---|
| AI powered discovery | Automated mapping of complex data relationships |
| Continuous tracking | Immediate visibility into data changes and flows |
| Infrastructure integration | Unified view of data across all systems |
The target: 90 percent of production objects covered by automated capture, with a monthly check that every registered connector is still reporting.
Table level lineage tells you that a report depends on a table. Column level lineage tells you that a specific figure depends on a specific field, which is the only granularity that answers a regulator, and the only granularity that lets you retire a column safely.
Column level lineage costs more to capture and to store, so the rule is to apply it by exposure rather than everywhere: 100 percent of assets carrying personal, financial or health data, 100 percent of anything feeding a regulatory report, and 100 percent of anything feeding a model or an AI agent. Everything else can stay at table level until there is a reason to deepen it. The column level lineage guide works through how that capture is built.
The AI case deserves its own line. When a model or an agent reads production data, the question after any bad output is which fields it saw and where they came from. Without column level lineage on those inputs, that question has no answer.
The target: 100 percent column coverage on regulated and model facing assets, table level elsewhere.
Lineage and data quality are usually run as two programs and they should be one. The graph is what turns a failed quality check from a notification into a diagnosis.
Define the metrics first: accuracy, completeness, consistency, timeliness and validity, measured at named points rather than everywhere. Attach the checks to lineage nodes so that a result is always attributable to a position in the path. Monitoring every step catches a problem before it propagates; monitoring only the output catches it after someone has already used the number.
Impact analysis is lineage read forwards. Before a schema change, a model rewrite or a source system migration, the graph lists every downstream consumer, which converts a change from a risk into a notification list. Make running it a required step in the change process rather than a courtesy, because the value only exists if it happens every time.
When a quality issue appears, lineage read backwards finds where it entered. Fixing it at that point rather than at the point of complaint is what stops the same issue returning next month in a different report. Record the root cause against the node, so the second occurrence is diagnosed in minutes.
The target: every critical data element carrying at least one automated quality check bound to its lineage node, and impact analysis as a mandatory gate in the change process.
Almost every lineage program measures the freshness of the data and forgets to measure the freshness of the lineage. A graph that is six weeks behind the pipeline produces plausible looking wrong answers, which does more damage than having no graph at all, because people act on what it tells them.
Measure the gap between a pipeline change landing and the graph reflecting it, and treat that gap as a service level. Under 24 hours is a reasonable target for production assets. Under an hour is what regulated reporting needs, because the question an examiner asks is about the state of the estate today. Publish the timestamp of the last successful capture next to the graph, so anyone reading it knows how much to trust it.
The target: freshness under 24 hours for production, under 1 hour for regulated reporting, with the last capture time visible to every consumer of the graph.
Regulatory expectations are the reason lineage gets funded in most regulated firms, and the expectation is consistent across supervisors: you must be able to show where a reported figure came from and demonstrate that the path is controlled.
Good data lineage documentation does four things for a compliance team. It evidences that data is accurate and reliable. It exposes risk in how data is handled. It makes audits an export rather than a reconstruction. It raises overall data quality, because documenting a path is how you discover the parts of it nobody understood.
The obligations worth naming, because most content on this topic names none of them or gets the dates wrong:
"Data lineage is the backbone of regulatory compliance in the digital age."
To stay ready rather than scrambling: run automated capture, keep documentation current as a matter of routine, train staff on the governance model rather than the tool, and audit the lineage process itself on a schedule.
The target: lineage documentation retained for at least the longest audit lookback that applies to you, version controlled, exportable without engineering involvement.
Every lineage platform demonstrates well, because every demonstration is run on a stack the vendor has already connected. The evaluation that predicts your outcome is narrower: take the five systems in your critical report path, and ask each vendor to produce column level lineage across all five in a trial on your data.
The capabilities worth scoring, and what each one actually changes:
| Feature | Importance | Impact on data management |
|---|---|---|
| Automated discovery | High | Reduces manual effort, improves accuracy |
| Continuous tracking | Medium | Enables quick issue detection and resolution |
| Integration capabilities | High | Ensures seamless data flow across systems |
| Customisable visuals | Medium | Enhances understanding of complex data relationships |
| Scalability | High | Supports long term data management growth |
Integration is the one to weight heaviest, because it is the only capability that cannot be worked around. A tool that cannot see your ingestion layer will never give you cross system coverage, no matter how good its graph looks. Our comparison of data lineage tools goes through the individual platforms in more detail than fits here.
The target: a trial on your own critical report path, scored on cross system coverage achieved, not on features demonstrated.
For a financial services firm, the best data lineage tool is the one that produces column level lineage across every system in the regulatory reporting path, retains that record for the full supervisory lookback, and attaches a named owner and a change history to each node. Visualization quality is a tiebreaker. Evidence is the requirement. A tool that draws a beautiful graph of your warehouse and cannot follow a figure into the regulatory report has not solved the problem the firm has.
Three questions decide the shortlist. Does it cover every system in the path, including ingestion and the reporting layer. Can it produce a record for a date in the past rather than only for today. Can a compliance officer export what a supervisor asks for without an engineer. If the answer to any of the three is no, the rest of the evaluation does not matter.
| Platform | Where it fits a financial services firm | The trade off to weigh |
|---|---|---|
| Decube | Governance, catalog, lineage and data quality in one platform, with column level lineage, ownership and quality results attached to the same nodes, so the evidence a supervisor asks for comes out of one system. Built with regulated markets in scope, including OJK, APRA, MAS and the NAIC framework. Pricing is published: Starter at 175 USD per user per month from 21,000 USD a year with a ten user minimum, Growth at 225 USD per user per month from 54,000 USD a year with a twenty user minimum. | A single platform means one vendor relationship rather than a best of breed stack, which suits teams that want governance consolidated and suits a very large bank with existing entrenched tooling less well. |
| Collibra | The established choice in large banks, with deep policy and workflow capability and a long track record with supervisors. | Implementation is a program rather than a project, and the cost and administrative overhead scale with it. Lineage depth often depends on additional connectors and services. |
| Alation | Strong catalog adoption and search, which matters when the goal is getting analysts to use governance rather than only to satisfy an auditor. | Its centre of gravity is the catalog and the community around it, so lineage depth across non warehouse systems needs checking carefully against your own stack. |
| Atlan | Modern interface, broad connector coverage and an active approach to column level lineage, which makes it a common shortlist entry for teams on a cloud native stack. | Positioned around the metadata layer, so quality monitoring and observability are more likely to be a separate purchase. |
| Informatica | Deep lineage through legacy ETL estates, which is genuinely valuable in a firm still running mainframe era pipelines alongside a cloud warehouse. | Heavy to run and priced for large estates. Strong where the legacy is, less natural on a modern stack. |
| OvalEdge | Lower cost entry point with catalog and lineage together, which suits mid market firms building a first governance capability. | Less depth for complex multi jurisdiction reporting obligations than the enterprise platforms above. |
| Native warehouse lineage | Free with the platform and accurate inside it. A reasonable starting point when the entire reporting path lives in one warehouse. | Stops at the warehouse boundary and carries fixed retention limits, which is exactly where a financial services reporting path usually goes next. See the section below. |
One caution on shortlisting. Regulated firms tend to select on brand familiarity, then discover during implementation that the coverage gap they were buying to close is still open because the ingestion layer was never connected. Run the trial on the real path.
Snowflake Horizon is enough for data lineage when everything you need to trace starts and ends inside Snowflake, one year of lineage history is enough for your audit obligations, and nobody needs to see how data got into Snowflake or where it went afterwards. Outside those three conditions you need a dedicated tool, because the native lineage does not cross the Snowflake boundary in either direction.
That is not a criticism of the feature. Snowflake documents its scope precisely, which is more than most vendors do. Lineage in Snowsight requires Enterprise Edition or higher. It covers object level lineage for table like objects and column level lineage between columns in those objects. Both object and column lineage are retained for one year. The documented exclusions matter: lineage is not available for objects in shared databases, the SNOWFLAKE database or INFORMATION_SCHEMA, temporary tables do not appear in the graph, deleted tables are not shown, and column lineage is not currently supported for semantic views.
| Capability | Snowflake Horizon native lineage | A dedicated lineage tool |
|---|---|---|
| Object and column lineage inside Snowflake | Yes | Yes |
| Lineage across ingestion, transformation and business intelligence tools | No | Yes |
| History retained beyond one year | No | Yes |
| Objects in shared databases | No | Partial |
| Temporary tables in the graph | No | Partial |
| Business glossary terms, ownership and stewards on each node | No | Yes |
| Edition requirement | Enterprise Edition or higher | Independent of your warehouse edition |
| Cost model | Included in the Snowflake contract | A separate subscription |
The decision rule is short. Draw your critical report path on one page. If every box on it is a Snowflake object, native lineage is enough and buying a tool is premature. If the path includes an ingestion tool, a transformation framework outside Snowflake, a dashboard, a second warehouse or a machine learning platform, the native graph will show you the middle of the path and neither end, which is the part of the question you needed answered. The same reasoning applies to the native lineage in any other warehouse platform: accurate within its own walls, silent outside them.
The retention limit is the second thing to check, and it is easy to miss. One year is generous for operations and short for supervision. If your audit lookback is longer than a year, native lineage cannot evidence the earlier period no matter how complete it is today.
Master data systems are the hardest place to keep lineage current, because a master record is never written once and left alone. Survivorship rules assemble it and then reassemble it from several source systems, and those rules themselves change over time. Lineage in that setting has to record not only which sources contributed, but which rule decided that a particular value won.
Four things keep it maintainable:
The target: attribute level lineage on every master data domain, rules under version control, and a recapture triggered by merge and reload events rather than on a schedule.
Most lineage programs fail in one of six recognizable ways. Each has a fix that is already one of the practices above, which is the argument for the order they are in.
| Challenge | What it looks like in practice | The fix |
|---|---|---|
| The graph goes stale | Lineage was mapped once during a project and nobody owns keeping it current | Automated capture plus a freshness target, practices 5 and 8 |
| Silent coverage gaps | Two source systems were never connected, so the graph is confidently wrong | Publish the coverage boundary as part of the record, and audit connectors monthly |
| Table level lineage that cannot answer a regulator | You can show a report depends on a table but not which field produced a figure | Column level lineage on regulated and model facing assets, practice 6 |
| No owner | Lineage belongs to engineering, analytics and risk jointly, so it belongs to nobody | A named technical owner and business steward per critical element, practice 3 |
| Manual documentation drift | The written record and the actual pipeline diverge within a quarter | Capture from code and query history rather than from descriptions, practice 5 |
| A tool that stops at the warehouse | Cross system questions cannot be answered because the graph covers one platform | Score integration breadth against your own critical path, practice 10 |
Data lineage best practices come down to one idea repeated at different scales: the record has to be produced automatically, kept current, and specific enough to answer the question that will actually be asked. Standards first, capture second, granularity by exposure, and tool selection last, once you know your own coverage gap.
The targets in this article are the version worth writing on a page and reviewing against each quarter: 90 percent automated coverage of production objects, 100 percent column coverage on regulated and model facing data, a graph refreshed within 24 hours, a named owner on every critical element, and retention that matches your audit lookback. A program that hits those five can answer a supervisor, a change review and an incident with the same record.
If you are deciding between extending what your warehouse gives you and running lineage as part of a governance platform, the boundary is the one described above: native lineage inside the warehouse, a dedicated tool the moment the critical path leaves it. Decube covers data lineage alongside cataloging, quality and governance in one platform, which is what makes the ownership and evidence trail land in the same place as the graph.
Data lineage is the recorded path a data asset takes from its origin, through every transformation applied to it, to every place it is consumed. It matters because it is the only way to answer three questions that otherwise take days: where did this figure come from, what breaks if I change this column, and can we evidence this number to an auditor. Without lineage, each of those becomes an investigation rather than a query.
A data lineage framework has five components: metadata management, which makes each node in the graph mean something; data flow mapping, which records the path between assets; impact analysis, which reads the graph forwards before a change; automated lineage discovery, which keeps the graph current without manual maintenance; and data quality monitoring, which binds check results to positions in the path. A gap in any one of them shows up later as a gap in the graph.
Data lineage standards are the written rules that make two teams document the same pipeline the same way. A usable standard covers five things: the metadata every asset must carry, the naming convention for systems, datasets and columns, the granularity required at each tier of criticality, who signs off a lineage record, and how often it is reviewed. Publish it as one page with a template attached, and set it before mapping begins, because retrofitting a naming convention across a live graph is work nobody gets funded to do.
A complete lineage record contains six things: the source of record at column level, the transformation logic captured from the code rather than described, the destinations and consumers down to the report, the business rule owner with a date, a versioned change history retained for the audit period, and an explicit statement of which systems are and are not in the graph. The last one is the one most teams skip, and a graph that silently excludes two source systems is worse than no graph because people trust it.
Data flow is the route data takes through a pipeline while that pipeline is running, and it answers where a job is now and what runs next. Data lineage is the stored historical record of which inputs produced which outputs, kept at table and column level, and it answers which report breaks if this column changes and where this value originally came from. An orchestration tool gives you data flow. It does not give you lineage, because it knows that task B follows task A but not that a specific column is derived from three columns in two source systems.
Snowflake Horizon is enough when everything you need to trace starts and ends inside Snowflake, one year of lineage history covers your audit obligations, and nobody needs to see how data got into Snowflake or where it went afterwards. Its lineage requires Enterprise Edition or higher, covers object and column level lineage for table like objects, and is retained for one year, with documented exclusions for shared databases, the SNOWFLAKE database and INFORMATION_SCHEMA, temporary tables, deleted tables and column lineage on semantic views. If your critical report path includes an ingestion tool, a transformation framework outside Snowflake, a dashboard or a second platform, you need a dedicated tool, because the native graph shows the middle of the path and neither end.
For a financial services firm the best data lineage tool is the one that produces column level lineage across every system in the regulatory reporting path, retains that record for the full supervisory lookback, and attaches a named owner and a change history to each node. Three questions decide the shortlist: does it cover every system in the path including ingestion and reporting, can it produce a record for a date in the past rather than only for today, and can a compliance officer export what a supervisor asks for without an engineer. Score the shortlist by running a trial on your own critical report path rather than on features demonstrated.
Score five capabilities: automated discovery, continuous tracking, integration breadth, visualization and scalability. Weight integration breadth heaviest, because it is the only one that cannot be worked around. A tool that cannot see your ingestion layer will never give you cross system coverage no matter how good its graph looks. Then run the evaluation on your own five most critical systems rather than on the vendor demonstration stack, and score it on coverage actually achieved.
Treat them as one system rather than two tools somebody reconciles. Capture metadata automatically from databases, files and applications and classify it as it arrives, hold it in a central repository covering sources, transformations and usage, and run automated discovery so the repository reflects the estate rather than the last manual update. Classification is the part that matters most, because an unclassified field carrying personal data will never be prioritized for column level lineage and nobody will notice until it is asked about.
Lineage turns a failed quality check from a notification into a diagnosis. Attach checks to lineage nodes so every result is attributable to a position in the path, then read the graph forwards for impact analysis before a change and backwards for remediation after an incident. Reading it forwards converts a schema change from a risk into a notification list. Reading it backwards finds where a problem entered, so it is fixed at the source rather than at the point of complaint.
Automated capture is the only lineage that stays true, because manual documentation drifts from the pipeline within a quarter. Discovery tooling parses transformation code and query history to find relationships nobody documented, including those in stored procedures and ad hoc scripts. Continuous tracking updates the graph as changes land rather than on a nightly rebuild, which is what makes a freshness target achievable. The second half matters too: audit the capture, because a connector that silently stops reporting looks exactly like a system with no dependencies.
It evidences that data is accurate and reliable, exposes risk in how data is handled, turns an audit into an export rather than a reconstruction, and raises data quality because documenting a path is how you find the parts of it nobody understood. GDPR Article 30 requires records of processing activities, BCBS 239 requires banks to evidence the traceability of risk data, and the EU AI Act assumes you can say what data trained or fed a system. Keep the documentation version controlled, because the question is rarely what the lineage is today, it is what the lineage was on the date of the report being investigated.
Record lineage at the attribute level rather than the record level, so you can say which source supplied a particular customer address rather than only which sources contributed to the customer. Version the match and survivorship rules alongside the data, because when a rule changes every record it touched changes meaning. Recapture after every merge, unmerge and reload, since those events rewrite relationships in bulk. Keep the golden record and its contributors linked in both directions, because consumers read the golden record while investigations have to walk back to the contributors.

First step to AI Readiness
Table of Contents
Sneak peek from the data world.


Bring lineage, quality, governance, and AI together in one platform—so your teams and AI agents can act with confidence.