Column Level Data Lineage: How It Works and What It Costs

What column level data lineage is, how it is derived from SQL, where parsing fails, what it costs to run, and the impact analysis it makes possible.

By

Jatin

Updated on

August 22, 2026

Key Takeaways

  • Column level lineage traces fields, not tables. Table level lineage tells you a report depends on a table. Column level lineage tells you which fields produced the number and which one of them moved.
  • It is derived, mostly by parsing SQL. Query logs and transformation manifests are read, the column mapping is extracted from each statement, and the results are stitched into a graph. This matters because parsing has known blind spots.
  • No tool reaches full coverage, and any that claims it is worth a second look. SQL built at runtime, stored procedures, user defined functions and transformations that never touch the warehouse all break the trace. Ask a vendor for coverage and confidence, not for a yes.
  • It is not free to compute or store. Cost tracks the number of columns, the volume of queries parsed, how often schemas change, and how much history you keep. Teams control it by scoping the highest risk tables first rather than the whole warehouse.
  • Two jobs earn its keep: impact analysis and root cause. Knowing exactly what breaks before you ship a change, and finding the field that broke after something already went wrong.
  • Supervisors ask a field level question. OJK, APRA, MAS and the NAIC all want to know how a specific reported number was produced. That is a column, not a table.

What Is Column Level Lineage?

Column level lineage is a record of how each individual field in your data platform was produced: which source fields fed it, what expression combined them, and which reports, models and downstream fields read it afterwards. It is the same idea as data lineage and its types, resolved one level finer, at the field rather than at the table.

That extra level changes what the record can answer. Table level lineage supports the question "what depends on this table". Column level lineage supports "what produced this number", which is the question a finance controller, an engineer about to drop a column and a supervisor all happen to ask in slightly different words.

The rest of this page stays on the column level question specifically: the difference you can feel in a worked example, how the trace is derived and where the derivation gives up, what it costs to run, and the two jobs it genuinely pays for.

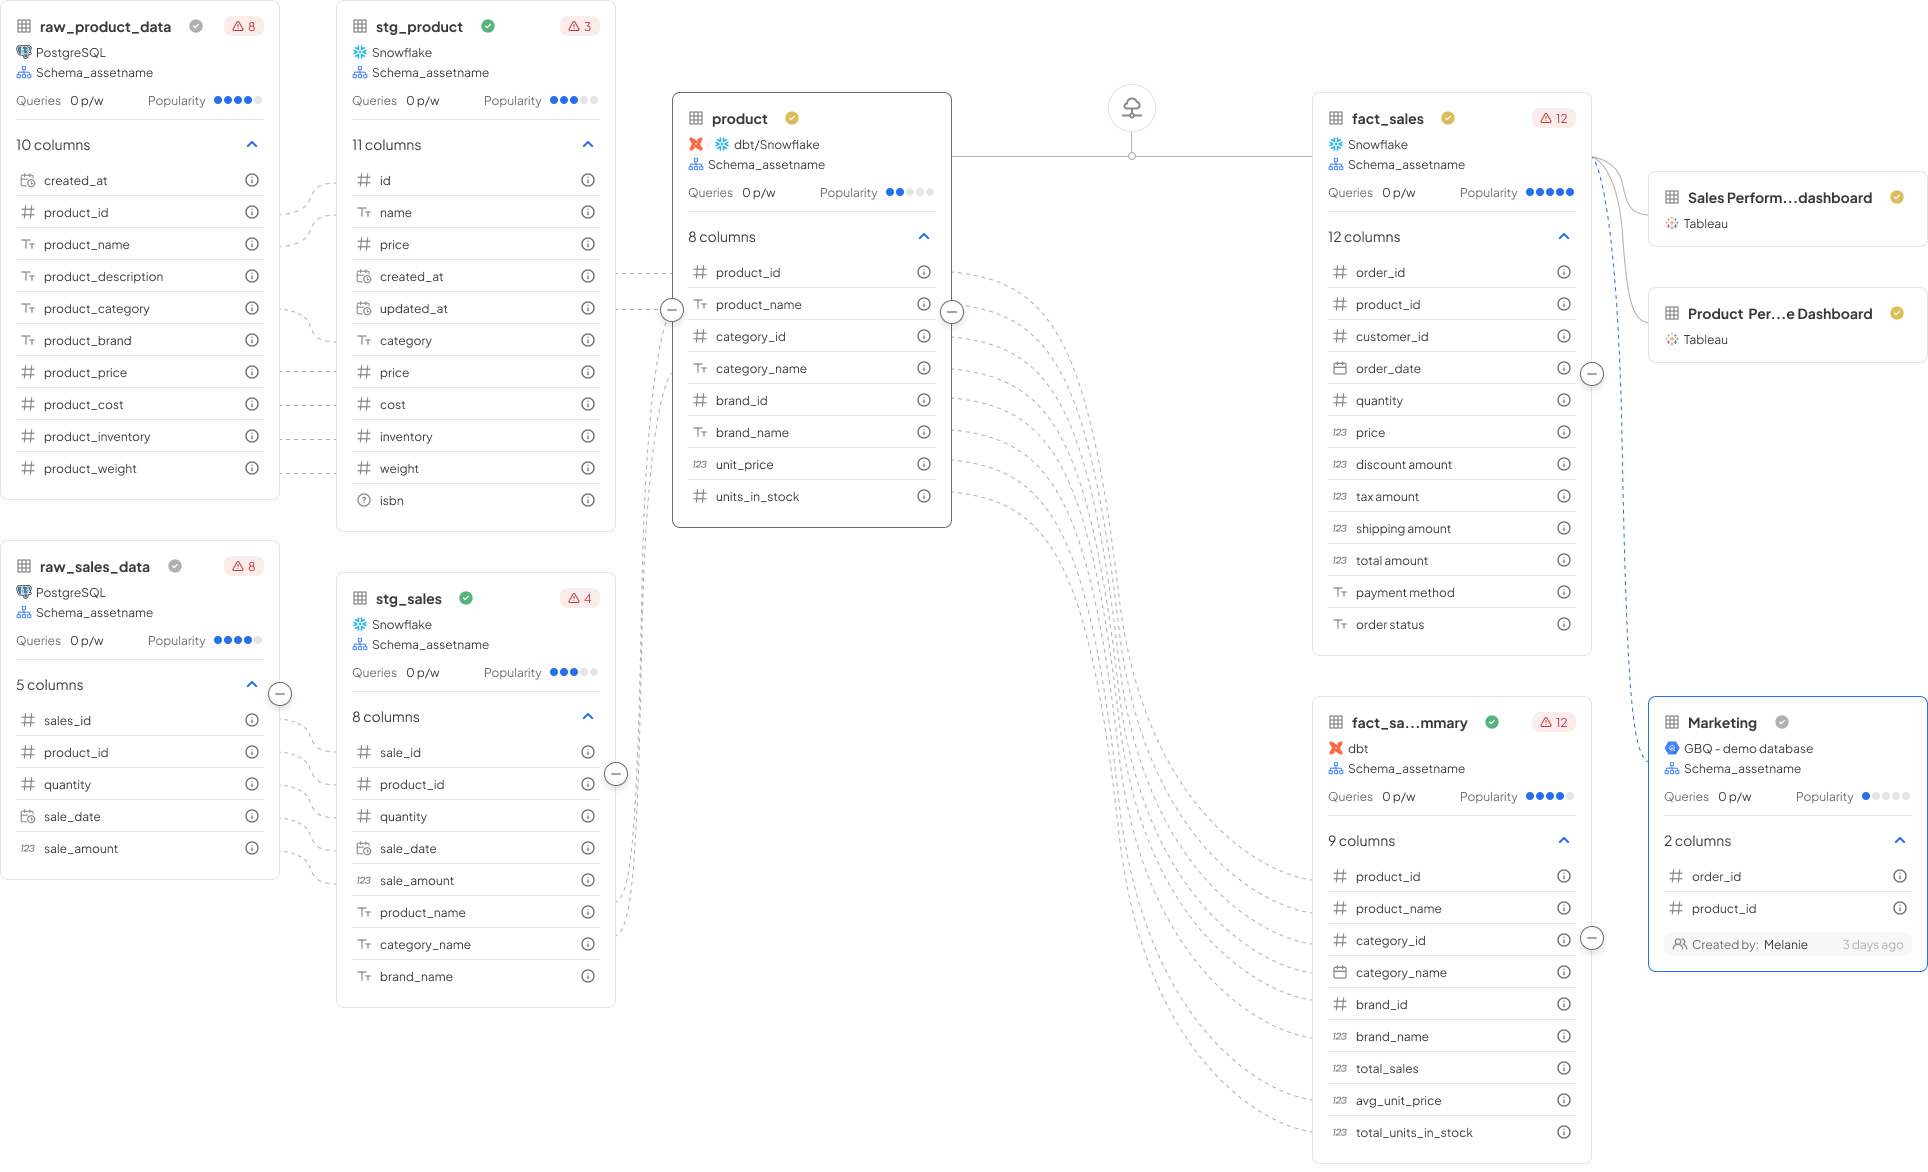
Column level lineage across a real stack. Every node is expanded to its field list, so the edges run from named columns in the PostgreSQL source tables through the Snowflake staging models into fact_sales and the Tableau dashboards, rather than from box to box.

Table Level or Column Level: A Worked Example

A finance team publishes a weekly revenue dashboard. On Tuesday morning the headline figure reads 4 percent lower than the same figure read on Monday. Nobody changed the dashboard. The question is what moved.

With table level lineage, the answer is that the dashboard reads from a revenue fact table, which reads from an orders staging table, a refunds staging table and a currency dimension. Three candidates, no ranking between them, and the next step is a person opening each transformation and reading the SQL by hand.
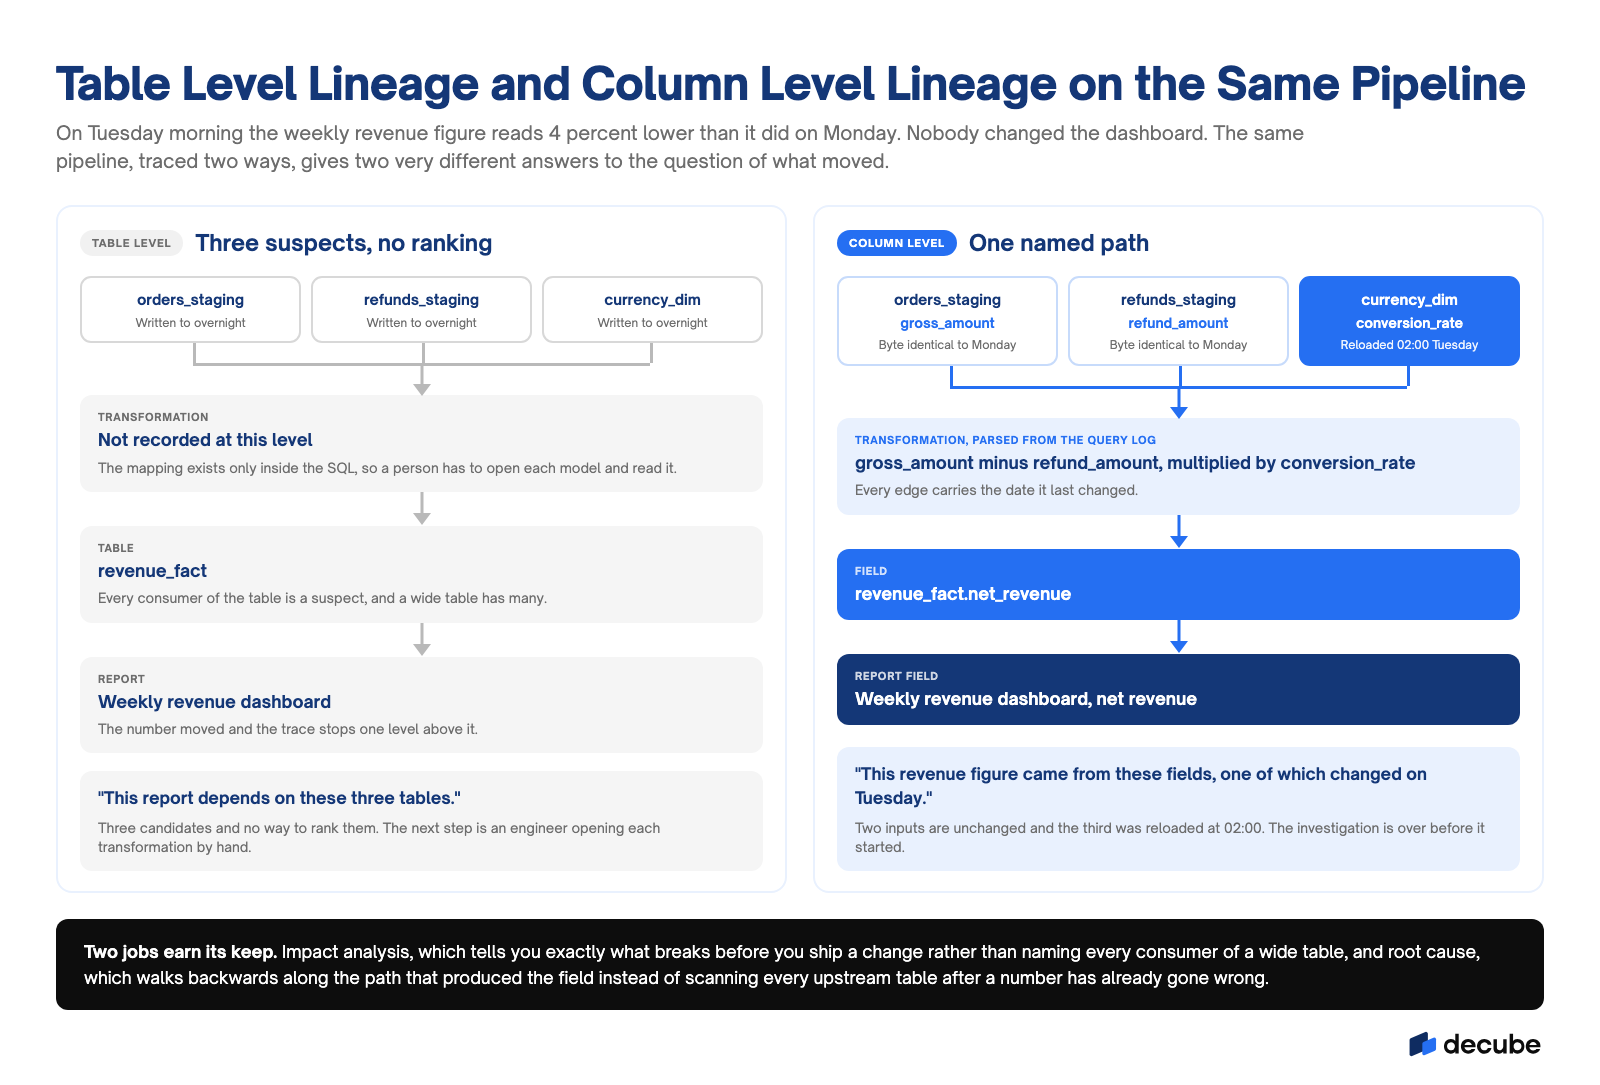
The same pipeline traced two ways: table level names three suspects, column level names one path.

With column level lineage, the answer names the path. The dashboard field is the net revenue column of the revenue fact table. That column is the gross amount from orders minus the refund amount from refunds, multiplied by the conversion rate held in the currency dimension. Three fields feed it, and the conversion rate was reloaded at 02:00 on Tuesday while the other two were unchanged. The investigation is over before it started.

That is the whole argument for field level tracing, and it repeats in every job below.

What the team is askingTable level answerColumn level answer
What produced this revenue figure?It depends on three upstream tables.It is gross amount minus refund amount, converted at the stored rate, and each of those is a named field in a named table.
What changed on Tuesday?One of the three upstream tables was written to.Only the conversion rate field was reloaded. The other two inputs are byte identical to Monday.
What breaks if we drop this column?Unknown. Every consumer of the table is a suspect.The exact list of downstream fields, reports and models that read this field, and nothing else.
Which reports contain customer personal data?Any report reading a table that holds a personal field.Only the reports where a personal field actually flows through to an output column.
Can we prove this number to an auditor?You can show the tables involved and then argue from the code.You can show the derivation of the number as a path, with a date on every edge.
How is the answer produced?A person opens each downstream query and reads it.The graph is queried and returns the path.

The Role of Column Level Lineage in Data Accuracy

Accuracy work fails in a predictable way. A test fires on a table, someone confirms the table is wrong, and then a day disappears into working out which field carried the error and how far it travelled. Column level lineage removes that middle day, because the path from the failing field back to its sources is already recorded.

It also changes what monitoring is worth. A freshness or volume check on a table tells you the table arrived. A check on a column tells you the field that feeds your reported number is still within range, and the lineage graph tells you which reported numbers move when it is not. That pairing of per column checks with per column lineage is what turns data observability from an alert stream into an answer.

The honest limit is that lineage records derivation, not correctness. It will show you that a revenue figure came from a conversion rate field. It will not tell you the rate was wrong. Lineage narrows the search; the tests still have to exist.

How Column Level Lineage Is Derived From SQL

Almost every column level graph in production is derived rather than declared. A tool collects the statements that ran, parses each one into a syntax tree, resolves the identifiers against the catalogue schema, and reads the column mapping out of the select list, the joins and the filters. Repeat that across every statement and the edges stitch into a graph.

Four sources feed that process, and most platforms combine them rather than picking one.

Source of the traceWhat it readsWhere it is strongWhere it stops
Query log parsingThe statements the warehouse actually executedIt sees what really ran, including ad hoc work and jobs nobody documented.It only sees SQL that reached the warehouse, and it needs log retention long enough to cover infrequent jobs.
Transformation manifestThe compiled model graph a transformation framework producesPrecise on modelled pipelines, and it knows the intent behind each model.It covers only what is inside that framework. Anything outside it is invisible.
Warehouse native metadataLineage the platform records about its own objectsCheap, already there, and accurate inside one platform.It ends at the platform edge, so the trace stops where the data leaves.
Declared mappingA mapping a person registers by handThe only option for a step no parser can read.It goes stale silently. Every declared edge needs an owner and a review date.

The practical consequence for a buyer is that "we have column level lineage" should be read as a coverage number over a defined scope rather than as a yes, and the scope is set by which of these four sources a tool actually reads. When you compare vendors, ask which sources they parse before you ask what the graph looks like. Our guide to the best data lineage tools works through that comparison in full.

Where SQL Parsing Fails and What to Do About It

No parser reaches complete coverage, and a vendor who says otherwise is describing a demo environment. The failures are well understood, they are the same ones in every platform, and each has a workable response. What separates a usable graph from a misleading one is whether the gaps are visible.

Where the trace is lostWhy the parser cannot follow itWhat to do instead
SQL assembled at runtimeThe statement text is built by application code, so the column names do not exist until the moment of execution.Parse the executed statement from the query log rather than the source code. What ran is always parseable, even when the code that produced it is not.
Stored proceduresA procedure holds branches, loops and temporary tables, so there is no single mapping from inputs to outputs to extract.Parse the statements the procedure emits at runtime where the log captures them, and declare the input to output mapping by hand where it does not.
User defined functionsThe function body may be written in another language and is opaque to a SQL parser.Register the signature and treat every output as derived from every input. It is coarser than the truth but it never misses a dependency.
Wildcard selectsThe parser cannot know which columns a star expands to without the schema as it stood when the query ran.Resolve against the catalogue schema at parse time and reparse when the schema changes. Track these separately, because they are the edges most likely to be silently wrong.
Transformations outside the warehouseWork done in Python, Spark jobs, notebooks or application code produces no SQL to read.Instrument the job so it emits its own lineage events, or accept a declared edge and mark its confidence lower so nobody mistakes it for a parsed one.
Calculations in the reporting layerThe metric is defined inside the business intelligence tool, after the data has left the warehouse.Pull the semantic model from the reporting tool and join it to the warehouse graph. Without this step the trace ends at the last table rather than at the number a person sees.

The response to all six is the same discipline. Score every edge as parsed, declared or inferred, publish coverage as a number per table tier, and treat a low confidence edge as a known gap rather than as a fact. A graph that admits what it does not know is more useful than one that quietly guesses, because only the first one tells you where to look by hand.

Benefits of Column Level Lineage

Column level lineage is often sold on a long list of benefits. In practice two jobs pay for it, and the rest follow from those two.

The two controls both jobs depend on. Upstream and downstream sets the direction of the trace, root cause reads one way and impact analysis the other, while the show all columns switch is what drops the view from table level to field level.

Impact analysis, before you ship

An engineer is about to rename a field, change its type, or drop it. Table level lineage returns every consumer of the table, which on a wide table is most of the business, so the answer is unusable and the change either stalls or ships blind. Column level lineage returns the fields, reports and models that read that one field. The review becomes a short list you can send to named owners, and the pull request carries the blast radius with it.

Root cause, after something broke

A number is wrong and the pressure is immediate. Column level lineage turns the search from a breadth first scan of every upstream table into a walk backwards along the path that produced the field, with the last change on each edge attached. The Tuesday example above resolves in one traversal.

What follows from those two

  • Personal data mapping that holds. Classify a source field as personal and the graph tells you every output field it reaches, which is a far smaller and far more defensible set than every report touching the table.
  • Deprecation you can finish. Fields with no downstream reader can be retired with evidence rather than left in place because nobody is sure.
  • Governance that produces proof rather than intent. A policy states which data a system may use. A field level trace shows what it used, which is what makes data governance evidence rather than assertion.
  • AI systems you can account for. When a model or an agent consumes a feature, the feature is a column. Extending the same trace forward into what an AI system did with it is the subject of agent lineage.

What Column Level Lineage Costs to Compute and Store

This is the question buyers ask and vendor pages avoid. A field level graph is more expensive than a table level one in every dimension, because the unit of work is the column and a warehouse has one or two orders of magnitude more columns than tables. The cost is manageable, but only if you know what drives it.

Cost driverWhy it costsHow teams control it
Column count, not table countThe graph grows with fields and with every version of every field, so a 400 column table is not one node, it is 400.Scope by table tier rather than by warehouse. Most teams find the tables that matter number in the dozens.
Volume of statements parsedEvery statement in scope has to be parsed, resolved against a schema, and reconciled with the existing graph.Parse a rolling window of recent activity for the whole estate, and keep deep history only for the tables you would have to defend.
Schema change frequencyA rename or type change invalidates every edge that touched the field and forces a reparse of the statements behind it.Reparse on a schedule and on schema change events rather than on every pipeline run.
History and versioningAnswering "what produced this number in March" needs the graph as it stood in March, which means storing versions rather than a current state.Keep full version history for regulated and financial tables, current state only for the rest.
Traversal at query timeDeep impact analysis walks many edges, and an interactive graph over a large estate is a real query workload.Precompute the traversals people actually run, usually one hop and full downstream from a field.

The scoping rule that works is risk first. Start with the tables behind numbers you would have to defend to a regulator, an auditor or a board: reported financials, revenue, customer records carrying personal data. Add the tables with the most downstream dependents next, because those are where an unnoticed change causes the widest damage. Everything else can run at table level until it earns the upgrade. A team that starts by pointing a lineage tool at the entire warehouse usually ends up paying for a graph nobody reads.

Implementing Column Level Lineage

The sequence below produces something people trust in weeks rather than a complete graph nobody has checked.

  • Pick the tables you would have to defend. Not the biggest tables and not the most queried. The ones behind numbers that leave the building. Expect a list of twenty to fifty.
  • Connect the query log first, the transformation manifest second. The log tells you what actually ran, including the jobs nobody documented. The manifest adds precision on top of it.
  • Parse, then score every edge. Mark each edge parsed, declared or inferred. Publish coverage per table tier as a number, and treat that number as the metric the project is judged on.
  • Close the known gaps by hand. Work the failure modes above in order. Every declared edge gets a named owner and a review date, or it will be wrong within a quarter.
  • Attach checks to the fields that matter. Lineage tells you where a problem travels; a check tells you a problem exists. Pair the graph with per column tests through a data observability tool so the two run against the same fields.
  • Widen by tier, not all at once. Extend to the next tier only after the first one is being used in change reviews. Coverage that nobody consults is cost without return.

Challenges in Achieving Column Level Lineage

  • Coverage is partial and the gaps are invisible by default. A graph that renders cleanly looks complete whether or not it is. If the tool does not show you what it failed to parse, you are reading a picture rather than a record.
  • Declared edges decay. Every hand mapped edge is a fact that was true once. Without an owner and a review date it becomes a confident error.
  • The trace ends at platform borders. Warehouse native lineage stops where the data leaves the warehouse, and the number a person actually sees is usually one step further on, inside a reporting tool.
  • Nobody owns the graph. Column level lineage is built by a platform team and used by analysts, engineers and compliance. Projects stall when it has no owner accountable for coverage, because coverage is the only thing that keeps it honest.
  • Cost arrives after the pilot. A pilot on ten tables is cheap and tells you nothing about the bill at five hundred. Ask for the cost model in columns and statements parsed, not per seat.

What a Regulator Asks For

Supervisors rarely use the phrase column level lineage. They ask how a specific reported number was produced, who is accountable for the data behind it, and whether the controls held on the date it was reported. Each of those is a field level question, and a table level answer does not close it.

SupervisorWho it coversWhat it asks that only a field level trace answers
OJK, IndonesiaBanks, insurers and financial technology firmsHow a figure in a supervisory return was produced, and whether the data behind it was controlled. The figure is a field, not a table.
APRA, AustraliaBanks, insurers and superannuation fundsControl over critical data elements with named accountability. A critical data element is a column, so the register and the lineage have to agree at that level.
MAS, SingaporeFinancial institutionsFairness, ethics, accountability and transparency for models that affect customers, which requires stating which input fields the model consumed.
NAIC, United StatesInsurers, at state levelDocumentation of underwriting and claims models. Rating variables are fields, and the question is where each one came from.

This is where the cost argument usually settles. A team can debate whether field level tracing is worth the compute for a marketing dashboard. For a number that goes to a supervisor, the alternative to a trace is an engineer reconstructing derivations by hand under a deadline, which is slower, more expensive and far less convincing.

Where Decube Fits

Decube derives column level lineage from the statements your warehouse actually ran and from your transformation models, then keeps per column checks on the same fields, so the graph and the monitoring agree rather than living in separate tools. Decube data lineage covers the trace itself, and the observability side adds the tests that tell you when a traced field has moved.

The part worth asking any vendor about, including us, is coverage. Ask which sources are parsed, what percentage of your scoped tables resolve to parsed rather than declared edges, and what the graph does with the transformations that never touch the warehouse. Request a demo if you want that answered against your own stack rather than against a sample one.

Frequently Asked Questions

What is column level lineage?

Column level lineage is a record of how each individual field was produced: which source fields fed it, what expression combined them, and which downstream fields, reports and models read it. It is data lineage resolved at the field rather than at the table, which is what lets it answer what produced this number rather than only what depends on this table.

What is the difference between column level lineage and table level lineage?

Table level lineage records that one table feeds another. Column level lineage records which fields carry that connection and how they were combined. The practical difference shows up in impact analysis: table level lineage tells you a change might affect every consumer of a wide table, while column level lineage returns only the fields and reports that read the one field you are changing.

Who provides data catalog solutions with column level lineage?

Decube provides column level lineage together with cataloguing and per column quality monitoring in one platform, which is what allows the lineage graph and the checks to run against the same fields. Several catalogue and observability vendors also offer it, at different coverage levels and with different pricing models. Our guide to the best data lineage tools compares them, including where each one derives its lineage from.

Can one platform combine data cataloging with column level access control?

Yes, and the two are more useful together than apart. Cataloguing tells you a field holds customer data, lineage tells you every output field it reaches, and access control then applies to the whole propagated set rather than only to the original table. Without lineage, column level access control has to be maintained by hand on each table someone remembers.

How do code centric analytics tools surface column level lineage and data quality metrics?

They read the code rather than the finished tables: the compiled model graph from a transformation framework gives the column mapping, and tests defined alongside the models produce the quality metrics. The strength is precision on modelled pipelines. The limit is scope, because anything outside that framework, including work done in notebooks or application code, is invisible unless the warehouse query log is parsed as well.

What is code level lineage?

Code level lineage traces data flow through application and transformation code rather than through executed SQL alone, which is how you cover steps written in Python, Spark or a stored procedure. It complements column level lineage rather than replacing it: the SQL parser produces the warehouse graph, and code level tracing fills the transformations the parser cannot read.

Does an active metadata platform need column level lineage?

It needs it to do the two jobs metadata platforms are bought for. Impact analysis at table level returns every consumer of a table, which is too broad to act on, and root cause analysis without field level paths still ends with an engineer reading SQL by hand. Table level lineage is enough for a catalogue that documents; column level is what a platform needs to answer questions.

See a Single Column Expanded to Its Downstream Mappings

The argument above stays abstract until you open a column and look at what it actually feeds. This two minute walkthrough opens the column level view on a lineage graph in Decube, expands one column to its downstream mappings so you can read which specific fields connect rather than which tables, and hovers an edge to show whether that relationship came from a Snowflake query or a dbt job. It also switches on the incident and classification layers, so PII and open data quality issues appear on the same nodes you are tracing. Useful if you are about to decide which of your own fields earn a field level trace first.

Is Atlan worth it?
Atlan is worth it if your primary need is a modern data catalog with strong column-level lineage and cloud-native integrations (Snowflake, dbt, Databricks). It is harder to justify if you also need data observability and quality coverage across a heterogeneous stack — those capabilities require separate vendors, adding cost and complexity.
What is the best Atlan alternative
Decube is purpose-built for regulated financial services, with native observability, approval-gated lineage, PII auto-classification, and an AI layer (TrustyAI) that does not route metadata to a public LLM. These map directly to regulatory frameworks supervised by MAS, OJK, BNM, and APRA. Atlan AI's OpenAI dependency is often a procurement blocker in these environments.
How does Atlan compare to Alation?
Both are catalog-first platforms with strong discovery. Alation pioneered search-first data culture and analyst adoption. Atlan is stronger on column-level lineage and cloud integrations. Both require external tooling for observability and broad data quality coverage.
How long does it take to migrate from Atlan to another platform?
Migration time depends on estate size and the number of active integrations. SaaS-native platforms like Decube deploy in 2–6 weeks without professional services. The longer task is typically re-establishing business glossaries, data ownership, and custom attributes — that effort is roughly the same regardless of which platform you move to.
What is the difference between a context layer and a semantic layer?
A semantic layer standardizes how metrics are defined and calculated so every analyst and BI tool uses the same numbers. A context layer encodes governance rules, data lineage, quality signals, and organizational knowledge so AI agents can make safe, autonomous decisions. The semantic layer is for human-facing analytics. The context layer is for AI-facing autonomy.
Can I use a semantic layer without a context layer?
Yes - and most organizations do today. If your primary consumers are human analysts using BI tools, a semantic layer alone is sufficient. The context layer becomes essential when you introduce AI agents that need to understand not just what a metric means but whether and how they are allowed to use it.
Is a context layer the same as a data catalog?
No. A data catalog is a component of a context layer. The catalog inventories data assets and stores metadata. The context layer activates that metadata by delivering it to AI agents at query time through APIs and MCP connections. Modern platforms like Atlan extend catalog functionality into full context layer infrastructure.
Which tool implements a context layer?
Purpose-built context layer platforms include Decube, which combines catalog, lineage, quality, and governance into a metadata layer that delivers context to AI agents via MCP. You can also build a context layer on custom infrastructure using a vector database (for semantic search), a knowledge graph
How long does it take to implement a context layer?
Most enterprise context layer implementations take 8–16 weeks when using a purpose-built platform like Atlan. Building from scratch on custom infrastructure typically takes 6–12 months. The timeline depends heavily on how much governance metadata already exists and how many data sources need to be connected.
What is Data Context?
Data Context is the information that explains what data means, where it comes from, how it is transformed, whether it can be trusted, and how it should be used. It combines metadata, lineage, data quality, and governance so people and systems can confidently use data for analytics, reporting, and AI.
How is Data Context different from metadata?
Metadata describes data, while Data Context makes data usable and trustworthy. Metadata provides definitions, ownership, and technical details. Data Context extends this by adding lineage, quality signals, and governance rules, creating a complete, operational understanding of data.
Why is Data Context important for AI?
AI systems require Data Context to interpret data correctly, safely, and reliably. Without context, AI models may misunderstand metrics, use stale or incorrect data, or expose sensitive information. Data Context ensures AI uses trusted, well-defined, and policy-compliant data.
How does data lineage contribute to Data Context?
Data lineage provides visibility into how data flows and transforms across systems. It shows upstream sources, downstream dependencies, and transformation logic, enabling impact analysis, root-cause investigation, and confidence in reported numbers.
How do organizations build Data Context in practice?
Organizations build Data Context by unifying metadata, lineage, observability, and governance into a single operational layer. This includes defining business meaning, capturing end-to-end lineage, monitoring data quality, and enforcing usage policies directly within data workflows.
What is Context Engineering?
Context Engineering is the practice of designing and operationalizing business meaning, data lineage, quality signals, ownership, and policy constraints so that both humans and AI systems can reliably understand and act on enterprise data. Unlike traditional metadata management, Context Engineering focuses on decision-grade context that can be consumed programmatically by AI agents in real time.
How is Context Engineering different from prompt engineering?
Prompt engineering focuses on how questions are phrased for an AI model, while Context Engineering focuses on what the AI system already knows before a question is asked. In enterprise environments, context includes data definitions, lineage, quality, and usage constraints—making Context Engineering foundational for trustworthy and scalable Agentic AI.
Why is Context Engineering critical for Agentic AI?
Agentic AI systems reason, decide, and act autonomously across multiple systems. Without engineered context—such as trusted data meaning, lineage, and real-time quality signals—agents cannot assess risk or impact correctly. Context Engineering ensures AI agents act safely, explain decisions, and know when to pause or escalate.
What are the core components of Context Engineering?
The four core components of Context Engineering are: Semantic context (business meaning and definitions) Lineage context (end-to-end data flow and dependencies) Operational context (data quality and reliability signals) Policy context (privacy, compliance, and usage constraints) Together, these form a unified context layer that supports enterprise decision-making and AI automation
How should enterprises prepare for Context Engineering?
Enterprises should follow a phased approach: Inventory critical data and trust gaps Unify metadata, lineage, quality, and policy into a single context layer Expose context through APIs for AI agent consumption By 2026, this foundation will be essential for deploying Agentic AI at scale with confidence and auditability.
How do you measure the ROI of a data catalog?
ROI is measured by comparing the quantifiable benefits (such as reduced data search time, fewer data quality issues, and lower compliance effort) against the total costs (implementation, licensing, and support). Typical metrics include time savings, productivity gains, and compliance cost reduction.
What is a data catalog and why is it important for ROI?
A data catalog is a centralized inventory of data assets enriched with metadata that helps users find, understand, and trust data across an organization. It improves data discovery, reduces search time, and enhances collaboration — all of which contribute to measurable ROI by cutting operational costs and accelerating insights.
How quickly can businesses see ROI after implementing a data catalog?
Time-to-value varies with deployment and adoption, but many organizations begin seeing measurable improvements in days to months, especially through faster data discovery and reduced compliance effort. Early wins in these areas can quickly justify the investment.
What factors should you include when calculating the ROI of a data catalog?
When calculating ROI, include: Implementation and training costs Recurring maintenance and licensing fees Savings from reduced data search and rework Compliance cost reductions Productivity and decision-making improvements This ensures a holistic view of both costs and benefits.
How does a data catalog support data governance and compliance ROI?
A data catalog enhances governance by classifying data, enforcing rules, and providing transparency. This reduces regulatory risk and compliance effort, leading to direct cost savings and stronger data trust.
What is data lineage?
Data lineage shows where data comes from, how it moves, and how it changes across systems. It helps teams understand the full journey of data—from source to final reports or AI models.
Why is data lineage important for modern data teams?
Data lineage builds trust in data by making it transparent and explainable. It helps teams troubleshoot issues faster, assess impact before changes, meet compliance requirements, and confidently use data for analytics and AI.
What are the different types of data lineage?
Common types of data lineage include: Technical lineage – Tracks data movement at table and column level. Business lineage – Connects data to business definitions and metrics. Operational lineage – Shows how pipelines and jobs process data. End-to-end lineage – Combines all of the above across systems.
Is data lineage only useful for compliance?
No. While data lineage is critical for audits and regulatory compliance, it is equally valuable for debugging data issues, impact analysis, cost optimization, and AI readiness.
How does data lineage help with data quality?
Data lineage helps identify where data quality issues originate and which reports or dashboards are affected. This reduces time spent on root-cause analysis and improves accountability across data teams.
What is Metadata Management?
Metadata management involves the management and organization of data about data to enhance data governance, data asset quality, and compliance.
What are the key points of Metadata Management?
Metadata management involves defining a metadata strategy, establishing roles and policies, choosing the right metadata management tool, and maintaining an ongoing program.
How does Metadata Management work?
Metadata management is essential for improving data quality and relevance, utilizing metadata management tools, and driving digital transformation.
Why is Metadata Management important for businesses?
Metadata management is important for better data quality, usability, data insights, compliance adherence, and improved accuracy in data cataloging.
How should companies evolve their approach to Metadata Management?
Companies should manage all types of metadata across different environments, leverage intelligent methods, and follow best practices to maximize data investments.
What is a data definition example?
A data definition example could be: “Customer: a person or entity that has made at least one purchase within the past year.” It clearly sets business meaning and inclusion criteria.
Why is data definition important in data governance?
It ensures everyone interprets data consistently, reducing ambiguity and improving compliance, reporting, and collaboration.
Who should own data definitions?
Ownership should be shared between business domain experts (for context) and data stewards (for technical accuracy).
How often should data definitions be reviewed?
Ideally quarterly or whenever there’s a structural change in business logic, data models, or product offerings.
What’s the difference between data definition and data catalog?
A data catalog inventories data assets; data definition explains what those assets mean. Combined, they create full visibility and trust.
Why is Data Lineage important for businesses?
Data Lineage provides transparency and trust in your data ecosystem. It helps organizations ensure data accuracy, simplify root-cause analysis during data quality issues, and maintain compliance with regulations like GDPR or SOX. By understanding data flows, teams can make faster, more reliable decisions and improve overall data governance.
What are the key components of Data Lineage?
The main components of Data Lineage include: Data Sources: Where the data originates (databases, APIs, files). Transformations: How data is processed or modified. Data Pipelines: The tools or systems that move data. Destinations: Where the data is stored or consumed (dashboards, reports, models). Metadata: The contextual details that describe each step in the data’s lifecycle.
How does Data Lineage support Data Governance and AI readiness?
Data Lineage acts as the foundation for strong data governance by providing visibility into data ownership, transformation logic, and usage. For AI initiatives, lineage ensures that models are trained on accurate and traceable data, making AI outputs more explainable and trustworthy. Platforms like Decube’s Data Trust Platform unify lineage with data quality and metadata management to help enterprises achieve AI readiness.
What tools are commonly used for Data Lineage?
Several tools help automate and visualize data lineage, such as Decube, Atlan, Alation, Collibra, and OpenLineage. These tools connect to data warehouses, ETL pipelines, and BI tools to automatically map relationships between datasets — saving time and reducing manual effort.
What is Data Lineage?
Data Lineage is the process of tracking how data moves and transforms across an organization — from its origin to its final destination. It shows where data comes from, how it changes through different systems or pipelines, and where it ends up being used. In short, data lineage helps you visualize the journey of your data.
What does “data context” mean?
Data context refers to the semantic, structural, and business information that surrounds raw data. It explains what data means, where it comes from, who owns it, and how it should be used.
What is a centralized LLM framework?
It’s an enterprise-wide system where all departments access AI through a shared platform, equipped with guardrails, context layers, and multimodal capabilities.
What are guardrails in AI?
Guardrails are controls—policies, access restrictions, and compliance checks—that ensure AI outputs are secure, ethical, and aligned with enterprise goals.
How does data context affect ROI in AI?
Models trained or prompted with contextualized data deliver outputs that are relevant, trustworthy, and actionable—leading to faster adoption and higher business value.
What is MCP (Model Context Protocol) and why does it matter?
MCP defines how models interact with external tools and data sources. Feeding it with strong context ensures the AI agent can act accurately and responsibly.
What is a Data Trust Platform in financial services?
A Data Trust Platform is a unified framework that combines data observability, governance, lineage, and cataloging to ensure financial institutions have accurate, secure, and compliant data. In banking, it enables faster regulatory reporting, safer AI adoption, and new revenue opportunities from data products and APIs.
Why do AI initiatives fail in Latin American banks and fintechs?
Most AI initiatives in LATAM fail due to poor data quality, fragmented architectures, and lack of governance. When AI models are fed stale or incomplete data, predictions become inaccurate and untrustworthy. Establishing a Data Trust Strategy ensures models receive fresh, auditable, and high-quality data, significantly reducing failure rates.
What are the biggest data challenges for financial institutions in LATAM?
Key challenges include: Data silos and fragmentation across legacy and cloud systems. Stale and inconsistent data, leading to poor decision-making. Complex compliance requirements from regulators like CNBV, BCB, and SFC. Security and privacy risks in rapidly digitizing markets. AI adoption bottlenecks due to ungoverned data pipelines.
How can banks and fintechs monetize trusted data?
Once data is governed and AI-ready, institutions can: Reduce OPEX with predictive intelligence. Offer hyper-personalized products like ESG loans or SME financing. Launch data-as-a-product (DaaP) initiatives with anonymized, compliant data. Build API-driven ecosystems with partners and B2B customers.
What is data dictionary example?
A data dictionary is a centralized repository that provides detailed information about the data within an organization. It defines each data element—such as tables, columns, fields, metrics, and relationships—along with its meaning, format, source, and usage rules. Think of it as the “glossary” of your data landscape. By documenting metadata in a structured way, a data dictionary helps ensure consistency, reduces misinterpretation, and improves collaboration between business and technical teams. For example, when multiple teams use the term “customer ID”, the dictionary clarifies exactly how it is defined, where it is stored, and how it should be used. Modern platforms like Decube extend the concept of a data dictionary by connecting it directly with lineage, quality checks, and governance—so it’s not just documentation, but an active part of ensuring data trust across the enterprise.
What is an MCP Server?
An MCP Server stands for Model Context Protocol Server—a lightweight service that securely exposes tools, data, or functionality to AI systems (MCP clients) via a standardized protocol. It enables LLMs and agents to access external resources (like files, tools, or APIs) without custom integration for each one. Think of it as the “USB-C port for AI integrations.”
How does MCP architecture work?
The MCP architecture operates under a client-server model: MCP Host: The AI application (e.g., Claude Desktop or VS Code). MCP Client: Connects the host to the MCP Server. MCP Server: Exposes context or tools (e.g., file browsing, database access). These components communicate over JSON‑RPC (via stdio or HTTP), facilitating discovery, execution, and contextual handoffs.
Why does the MCP Server matter in AI workflows?
MCP simplifies access to data and tools, enabling modular, interoperable, and scalable AI systems. It eliminates repetitive, brittle integrations and accelerates tool interoperability.
How is MCP different from Retrieval-Augmented Generation (RAG)?
Unlike RAG—which retrieves documents for LLM consumption—MCP enables live, interactive tool execution and context exchange between agents and external systems. It’s more dynamic, bidirectional, and context-aware.
What is a data dictionary?
A data dictionary is a centralized repository that provides detailed information about the data within an organization. It defines each data element—such as tables, columns, fields, metrics, and relationships—along with its meaning, format, source, and usage rules. Think of it as the “glossary” of your data landscape. By documenting metadata in a structured way, a data dictionary helps ensure consistency, reduces misinterpretation, and improves collaboration between business and technical teams. For example, when multiple teams use the term “customer ID”, the dictionary clarifies exactly how it is defined, where it is stored, and how it should be used. Modern platforms like Decube extend the concept of a data dictionary by connecting it directly with lineage, quality checks, and governance—so it’s not just documentation, but an active part of ensuring data trust across the enterprise.
What is the purpose of a data dictionary?
The primary purpose of a data dictionary is to help data teams understand and use data assets effectively. It provides a centralized repository of information about the data, including its meaning, origins, usage, and format, which helps in planning, controlling, and evaluating the collection, storage, and use of data.
What are some best practices for data dictionary management?
Best practices for data dictionary management include assigning ownership of the document, involving key stakeholders in defining and documenting terms and definitions, encouraging collaboration and communication among team members, and regularly reviewing and updating the data dictionary to reflect any changes in data elements or relationships.
How does a business glossary differ from a data dictionary?
A business glossary covers business terminology and concepts for an entire organization, ensuring consistency in business terms and definitions. It is a prerequisite for data governance and should be established before building a data dictionary. While a data dictionary focuses on technical metadata and data objects, a business glossary provides a common vocabulary for discussing data.
What is the difference between a data catalog and a data dictionary?
While a data catalog focuses on indexing, inventorying, and classifying data assets across multiple sources, a data dictionary provides specific details about data elements within those assets. Data catalogs often integrate data dictionaries to provide rich context and offer features like data lineage, data observability, and collaboration.
What challenges do organizations face in implementing data governance?
Common challenges include resistance from business teams, lack of clear ownership, siloed systems, and tool fragmentation. Many organizations also struggle to balance strict governance with data democratization. The right approach involves embedding governance into workflows and using platforms that unify governance, observability, and catalog capabilities.
How does data governance impact AI and machine learning projects?
AI and ML rely on high-quality, unbiased, and compliant data. Poorly governed data leads to unreliable predictions and regulatory risks. A governance framework ensures that data feeding AI models is trustworthy, well-documented, and traceable. This increases confidence in AI outputs and makes enterprises audit-ready when regulations apply.
What is data governance and why is it important?
Data governance is the framework of policies, ownership, and controls that ensure data is accurate, secure, and compliant. It assigns accountability to data owners, enforces standards, and ensures consistency across the organization. Strong governance not only reduces compliance risks but also builds trust in data for AI and analytics initiatives.
What is the difference between a data catalog and metadata management?
A data catalog is a user-facing tool that provides a searchable inventory of data assets, enriched with business context such as ownership, lineage, and quality. It’s designed to help users easily discover, understand, and trust data across the organization. Metadata management, on the other hand, is the broader discipline of collecting, storing, and maintaining metadata (technical, business, and operational). It involves defining standards, policies, and processes for metadata to ensure consistency and governance. In short, metadata management is the foundation—it structures and governs metadata—while a data catalog is the application layer that makes this metadata accessible and actionable for business and technical users.
What features should you look for in a modern data catalog?
A strong catalog includes metadata harvesting, search and discovery, lineage visualization, business glossary integration, access controls, and collaboration features like data ratings or comments. More advanced catalogs integrate with observability platforms, enabling teams to not only find data but also understand its quality and reliability.
Why do businesses need a data catalog?
Without a catalog, employees often struggle to find the right datasets or waste time duplicating efforts. A data catalog solves this by centralizing metadata, providing business context, and improving collaboration. It enhances productivity, accelerates analytics projects, reduces compliance risks, and enables data democratization across teams.
What is a data catalog and how does it work?
A data catalog is a centralized inventory that organizes metadata about data assets, making them searchable and easy to understand. It typically extracts metadata automatically from various sources like databases, warehouses, and BI tools. Users can then discover datasets, understand their lineage, and see how they’re used across the organization.
What are the key features of a data observability platform?
Modern platforms include anomaly detection, schema and freshness monitoring, end-to-end lineage visualization, and alerting systems. Some also integrate with business glossaries, support SLA monitoring, and automate root cause analysis. Together, these features provide a holistic view of both technical data pipelines and business data quality.
How is data observability different from data monitoring?
Monitoring typically tracks system metrics (like CPU usage or uptime), whereas observability provides deep visibility into how data behaves across systems. Observability answers not only “is something wrong?” but also “why did it go wrong?” and “how does it impact downstream consumers?” This makes it a foundational practice for building AI-ready, trustworthy data systems.
What are the key pillars of Data Observability?
The five common pillars include: Freshness, Volume, Schema, Lineage, and Quality. Together, they provide a 360° view of how data flows and where issues might occur.
What is Data Observability and why is it important?
Data observability is the practice of continuously monitoring, tracking, and understanding the health of your data systems. It goes beyond simple monitoring by giving visibility into data freshness, schema changes, anomalies, and lineage. This helps organizations quickly detect and resolve issues before they impact analytics or AI models. For enterprises, data observability builds trust in data pipelines, ensuring decisions are made with reliable and accurate information.

Table of Contents

Read other blog articles

Grow with our latest insights

Sneak peek from the data world.

Thank you! Your submission has been received!
Talk to a designer