Enroll to explore sandbox
Kindly fill up the following to try out our sandbox experience. We will get back to you at the earliest.
Kindly fill up the following to try out our sandbox experience. We will get back to you at the earliest.
Data mesh architecture explained as four planes and four principles: what each one requires, what breaks without it, and who owns it. Plus the build order.

Updated on
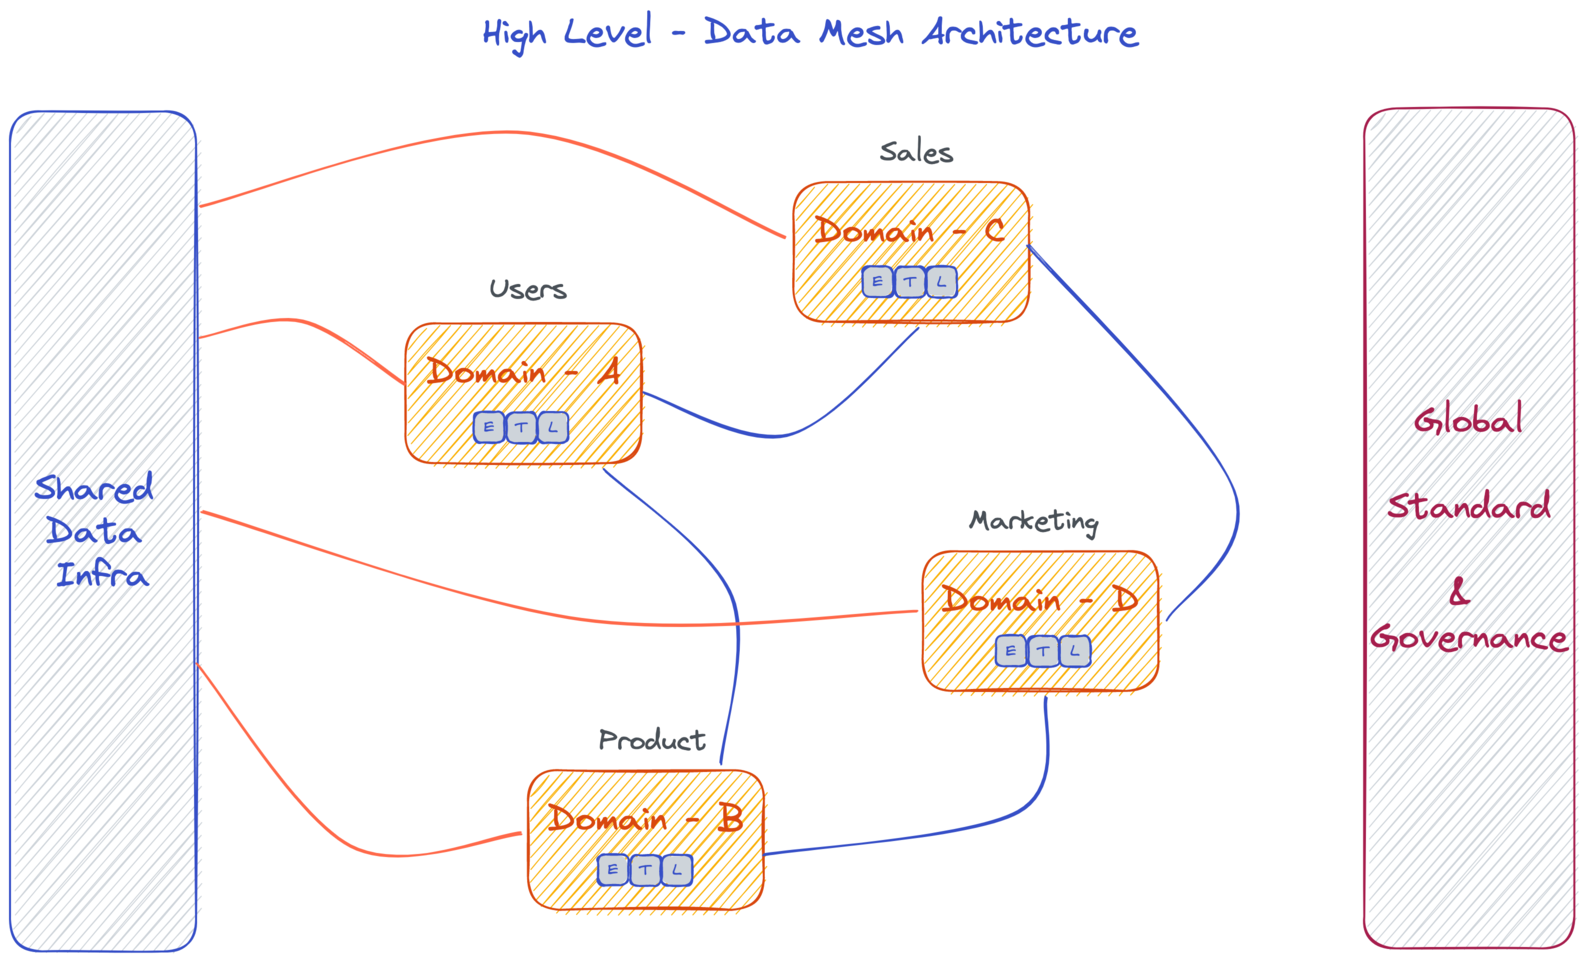
Data mesh architecture arranges analytical data so that the team who already owns a business domain also owns the data that domain produces, publishes it as a product other teams can use without asking permission, and does so on a shared platform that applies one set of governance rules automatically. That is the whole idea. The rest of this article is about how it is built: the planes the architecture is made of, what each of the four principles requires you to construct, the order the work happens in, the ways it fails, and the conditions under which you should not attempt it. For the definition itself, where the idea came from and how it compares with a warehouse or a lake, read what a data mesh is and where the idea came from.
Most data mesh diagrams are drawn as a grid of hexagons connected by arrows, which looks organized and explains nothing. The useful way to draw it is as four horizontal planes stacked on top of each other, because the planes are what differ from a centralized architecture. In a warehouse or lake diagram there is one pipeline plane and one storage plane, and both belong to the central data team. In a mesh, the ownership boundary runs vertically through the middle of the picture instead: the domains own the first two planes, and a central team owns the two that support them.
Read the table below as the diagram. Each row is a plane. Arrows in a drawing would run upward from row one to row two, because a domain turns its own operational data into a product; sideways between the data products in row two, because a domain can consume another domain's product directly rather than going through a central store; and from rows three and four into rows one and two, because the platform and the governance rules apply to every domain equally.
| Plane | What sits in it | Who owns it | What it publishes |
|---|---|---|---|
| 1. Operational domain systems | The applications and databases that run the business: orders, payments, claims, shipments, the customer record. Nothing here changes when you adopt a mesh. | The engineering team that already owns the application | Raw operational events and tables, unchanged, to the domain that produced them |
| 2. Domain data products | The analytical output each domain publishes for everybody else: modelled tables, event streams, aggregates, and the documentation, schema contract and quality checks attached to each one | A named data product owner inside the business domain, supported by the domain's own data engineers | Addressable, documented, versioned data products that any other domain can find and consume without filing a ticket |
| 3. Self serve data platform | Everything a domain would otherwise have to build for itself: storage and compute, pipeline templates, the catalog, lineage, quality monitoring, access control, deployment pipelines. Domain agnostic by design. | A central data platform team, whose customers are the domain teams | Paved paths. A domain can create, publish, monitor and retire a data product without a central team writing any of it. |
| 4. Federated governance | The global rules every product obeys: naming and identifier standards, classification, privacy and retention, interoperability, and the minimum quality bar for publication | A council of domain representatives plus the platform team, security and legal | Policies expressed as code that the platform applies at publish time, and a catalog record proving each product complied |
The single test that separates a real mesh diagram from a relabeled warehouse diagram is row four. If your governance plane produces a document rather than a check that runs, the architecture is centralized governance with decentralized storage, which is the worst of both arrangements.
The four principles were set out by Zhamak Dehghani, who defined the model while at ThoughtWorks, and they are usually presented as values. Presented that way they are impossible to act on, because a value cannot be checked off. The table below restates them as a specification: what each principle obliges you to build, what specifically breaks if you skip it, and who is accountable. Her original write up of the four principles remains the reference text if you want the reasoning behind them.
| Principle | What it requires you to build | What breaks without it | Who owns it |
|---|---|---|---|
| 1. Domain oriented ownership | A published map of business domains; one named data product owner per domain; the domain's analytical pipelines moved into the domain's own repository, deployment process and on call rotation | Data stays with a central team that does not know what the fields mean. Every change queues behind that team, and that queue is the bottleneck a mesh exists to remove. Renaming the central team does not move the queue. | The engineering leader of each domain, with the chief data officer accountable for the domain map itself |
| 2. Data as a product | A publication standard every domain must meet before its output is visible to anyone else: owner, definition, stable address, versioned schema contract, quality threshold, lineage, access policy, support channel | Domains publish raw tables with no documentation and no promises. Consumers cannot tell a certified product from a scratch table, so they ask a person, and you have rebuilt the ticket queue inside a decentralized architecture. | The data product owner in the domain, who is accountable to consumers for the product behaving as documented |
| 3. Self serve data platform | Paved paths: templates and automation for ingestion, modeling, testing, publication, monitoring, access requests and decommissioning, usable by a domain engineer who is not a data platform specialist | Every domain builds its own version of the same pipeline, monitoring and access control. Costs multiply by the number of domains, and no two products behave the same way, so nothing is comparable across the mesh. | The central data platform team, measured on adoption of the paved paths rather than on tickets closed |
| 4. Federated computational governance | A governance council with domain representation, a small set of global rules, and the enforcement of those rules as automated checks inside the publication pipeline | Twelve domains invent twelve definitions of customer and twelve ways of masking an email address. Cross domain analysis becomes impossible and no regulator can be answered, because no single record shows who could read what. | The council collectively, with the platform team responsible for turning each agreed rule into a check that runs |
In a data mesh architecture, data is organized into smaller, manageable domains. Each domain represents a specific business area or function and is owned by a dedicated team, so domain experts take full responsibility for their data assets rather than handing them to a central group to interpret. In practice the boundary that works is the one the business already uses: if orders, payments and fulfilment have separate engineering teams and separate systems, they are separate domains, and no amount of data modeling will make them one. Martin Fowler's piece on domain oriented observability is a useful companion here, because the same argument about instrumenting a system along its business boundaries applies to the data that comes out of it.
The artefact this principle produces is a domain map with a named owner against every entry and a date the ownership was last confirmed. If you cannot produce that map, you do not have domain ownership, whatever the architecture diagram says.
A data mesh treats data as a product rather than as a byproduct of an operational system. Each domain team is responsible for providing well defined, high quality data products that are discoverable, addressable and consumable by other teams without a conversation. The word product is doing real work in that sentence: a product has a customer, a version, a promise about how it behaves, and someone who answers when it stops behaving that way.
The eight attributes below are the publication standard. A domain either meets all eight or its output is not published to the mesh. Most of them are metadata a data catalog already holds; the ones teams skip are the quality threshold and the support channel, which are the two that decide whether anybody trusts the product.
| Attribute | What done looks like | Where it lives |
|---|---|---|
| Named owner | A person, not a team alias, with a deputy named for absence | Catalog entry and the domain map |
| Business definition | What the product represents in business terms, including what it deliberately excludes | Catalog entry and the business glossary |
| Stable address | One canonical location and name that does not change when the underlying storage does | Catalog entry |
| Versioned schema contract | The columns, types and semantics consumers can rely on, with a stated notice period before a breaking change | Version controlled next to the pipeline code |
| Published quality threshold | Numbers, not adjectives. Maximum age of the data, minimum row count, the null rate allowed on each key column, and the uniqueness rule on the primary key. | Quality monitoring, with the current state shown on the catalog entry |
| Lineage | Column level, upstream to the operational source and downstream to consumers | Lineage graph, generated rather than drawn by hand |
| Access policy and classification | Sensitivity class on every column, and a rule stating who is granted access on what basis | Governance policy, applied by the platform |
| Support channel and change notice | Where a consumer reports a problem, the response time they can expect, and how they are told before something changes | Catalog entry |
The video above shows the mechanics of the curation step: a producer names a product, describes it, assigns owners, attaches the underlying assets, then publishes it to a marketplace where consumers can browse it, read the documentation, ask questions and rate it. That rating loop is the part most implementations leave out, and it matters, because in a mesh nobody has the authority to tell another domain that its product is good. Decube's data products module is where that publication standard is applied in our own platform.
A data mesh depends on self serve data infrastructure: tools and platforms that let domain teams independently create, publish and consume data products, which reduces the dependencies between teams and lets them work at their own pace. The measure of whether the platform is genuinely self serve is simple. Take a domain engineer who has never built a data product, and see whether they can ship one to the standard above without anyone from the platform team writing code for them. If they cannot, the platform is a shared service with a new name.
A platform is ready when it provides all of the following as paved paths: ingestion from the domain's own systems, a modeling and testing framework, automated publication to the catalog with the metadata already attached, quality monitoring configured from the declared thresholds, lineage captured automatically rather than documented by hand, an access request and approval process, cost attribution back to the domain, and a decommissioning path so retired products actually disappear. The last one is the one everybody forgets, and it is why meshes accumulate abandoned products that consumers keep querying for years.
A data mesh adopts federated governance, which means governance policies and practices are set centrally but applied across the organization in a decentralized way, so each domain team can tailor its own practices while still meeting organization wide standards. The distinction that decides whether this works is between a policy that is written down and a policy that is computational. A written policy says customer identifiers must be masked in non production environments. A computational policy is a check in the publication pipeline that refuses to publish a product containing an unmasked identifier. Only the second one survives contact with twelve teams under delivery pressure. Mesh-AI's primer on federated data governance works through the operating model in more detail.
Keep the global rule set small. The rules that genuinely have to be global are the ones that make products interoperable or keep you lawful: identifier standards so two domains can be joined, classification and masking, retention and deletion, the minimum quality bar for publication, and the requirement that lineage exists. Everything else belongs to the domain. Decube's data governance module holds the policy and classification side of that, and column level data lineage is what makes the enforcement checkable, because a rule about where data may travel is unenforceable if nobody can show where it travelled.
The differences worth knowing are structural rather than technological. A mesh can run entirely on the same warehouse a centralized architecture uses; what changes is who is accountable for what, and where the checks run.
| Dimension | Central warehouse or data lake | Data mesh |
|---|---|---|
| Who models the data | A central data team, working from requirements and its own reading of the source systems | The domain that produced the data, which already knows what the fields mean |
| Where the bottleneck sits | The central team's backlog. Every new question waits behind every other question. | The platform team's ability to keep paved paths working. If the paths are good, domains do not queue. |
| What a consumer receives | A table in a shared schema, documented as well as the central team had time for | A product with a named owner, a version, a published quality threshold and a support channel |
| How governance is applied | Centrally, by the team that also builds the pipelines, so the rules and the delivery pressure sit in the same place | Centrally agreed, automatically applied at publish time by the platform, independently of who built the product |
| What happens when the business reorganizes | The models break and the central team rewrites them | The domain boundary moves and its products move with it, because ownership follows the business |
| Cost of getting it wrong | Slow delivery and a large backlog, which is visible and survivable | Twelve incompatible definitions of the same entity, which is invisible until somebody tries to join two domains |
Implementing a data mesh requires a shift in mindset, organizational structure and technology choices, in that order. The order matters more than the list, because every step below depends on the one above it, and the common failure is starting at step four. Shantanu De's practical guide to data mesh implementation is a useful second reading once the domain map exists.
Identify the data domains and establish dedicated domain teams. Write down every domain, the systems it owns, the person accountable for its data and the products it will eventually publish. Argue about the boundaries now, while the argument is free. If two candidate domains cannot agree who owns the customer record, that is not a modeling problem to be solved later, it is the single most important decision in the program.
Define and catalog data products, which means agreeing the eight attributes above and writing them down as the condition of publication. Doing this second, before any product exists, is what stops the mesh filling with undocumented tables that are politically hard to remove later.
Adopt the storage and processing technologies you need and implement the self serve infrastructure, but build it for a single pilot domain first. A platform designed in the abstract for twelve hypothetical domains is always wrong. A platform that has carried one real domain to publication is a starting point you can generalise.
Take one domain through the whole path: model, test, document, set the quality thresholds, publish, then find a consuming team and let them build something on it. The first genuine consumer is what tells you whether the standard is meaningful or ceremonial, and it is the only reliable way to find out what the platform is missing.
Form the council, agree the small global rule set, then turn each rule into a check that runs in the publication pipeline. A rule that has not been implemented as a check is not a policy yet, it is an intention. Doing this at step five rather than step one is deliberate: you now know what the rules have to constrain, because you have watched one product go through the pipeline.
Onboard the remaining domains individually, and track the number of products that meet the publication standard rather than the number of products that exist. The second number always grows faster and means nothing. A mesh with forty products and no quality thresholds is worse than the warehouse it replaced, because it has the same problems and no single team who can fix them.
A data mesh helps because it removes the queue. A traditional architecture stores data in one place under one small team of experts, which creates bottlenecks, limits access and slows decisions. A mesh distributes ownership across the organization and treats data as a product, so data stops being hidden behind a request process and becomes something teams can find and use. Six benefits follow from that, and they follow in this order:
The honest caveat is that all six are consequences of the model working, not of the model existing. A mesh that is announced but not enforced produces none of them, and the failure modes below are how you tell the difference early.
None of the pages currently ranking for this term will tell you what goes wrong. These are the five failures that actually occur, each with a test you can run this week.
| Failure mode | What it looks like | The test |
|---|---|---|
| The relabeled warehouse | The central team is renamed the platform team and keeps building every pipeline. The diagram changed and nothing else did. | Count the pull requests to domain data pipelines in the last month and check how many were authored by someone outside the platform team. If the answer is near zero, you do not have a mesh. |
| Products without promises | Domains publish tables with a title and no quality threshold, no owner and no contract. | Pick five published products at random and try to find, for each, the maximum age of the data and the person accountable. If you cannot do it in two minutes each, the publication standard is not being applied. |
| Governance that is only a document | Policies exist in a wiki. Nothing checks them at publish time. | Try to publish a product containing an unmasked sensitive column. If it publishes, the governance plane is not computational. |
| Twelve definitions of the same entity | Two domains report different revenue for the same period and both are correct inside their own definition. | Ask two domains to produce the count of active customers for the same date. If the numbers differ, find out whether the difference is documented. Undocumented is the failure, not the difference itself. |
| A platform nobody can use alone | Domains ask the platform team for help on every product, so the queue reappears in the support channel instead of the backlog. | Give a domain engineer who has never done it the task of publishing a product, and time it. If they need platform team code rather than platform team advice, the paved paths are not finished. |
A data mesh is an organizational change delivered through technology, and it costs more coordination than a central team does. It is worth that cost only when the central team is genuinely the constraint. Our test before recommending one is three conditions, and all three have to hold:
If any one of those is missing, a well governed central warehouse with a real data catalog and published ownership will serve the same business need at a fraction of the cost. That is not a compromise, it is the correct architecture for that situation, and you can move to a mesh later once the conditions hold.
Data mesh architecture has been adopted by organizations across industries. Two accounts are worth reading in full because both describe the organizational work rather than only the technology: how JPMorgan Chase built a data mesh architecture on its enterprise data platform, and ThoughtWorks' own account of the shift to data mesh and what it changed.
Both illustrate the same point about data lakes, which is where most meshes begin. A lake is not the opposite of a mesh; it is frequently the storage underneath one. What changes is that data owners are assigned to specific domains, so responsibility and accountability for the quality and governance of each dataset has a name against it, and federated policies and security controls apply to the lake automatically rather than being administered by hand. The self serve infrastructure is what lets business teams reach that data themselves, which is the actual source of the speed, while the classification and access rules keep the lake protected.
A mesh needs three things from a platform and they are the three that are hardest to build in house: a place products are published and found, a record of where data came from that nobody maintains by hand, and policies that run rather than sit in a document. Decube covers all three in one platform. Data products is the curation and marketplace layer where a domain packages assets into a documented, owned and rated product. Column level data lineage is generated from the pipelines themselves, which is what makes an access or retention rule checkable across domain boundaries. Data governance holds the classification and policy side, applied consistently no matter which domain published the product.
The reason those three belong together rather than in three tools is that a mesh multiplies the number of places a rule has to be applied. One domain with three tools is manageable. Twelve domains with three tools is twelve times the integration work, and it is usually the point at which federated governance quietly stops being enforced. If you want to see how the publication standard in this article maps onto a working platform, request a demo and bring one of your own domains to it.
Both are worth the time: Data Mesh: A Paradigm Shift in Big Data Management and Data Mesh Learning. Reading how other teams did it is the cheapest research available on this subject, because almost every failure listed earlier in this article has already been written up by somebody who lived through it.
Data mesh architecture answers a real problem, which is that a central data team cannot know what every field in every system means and should not be asked to. Adopting domain oriented ownership, data as a product, self serve infrastructure and federated governance lets teams work autonomously on data at a scale a central group cannot serve. But the model only pays for itself when all four principles are built, because each one exists to contain the risk another one creates.
If you are starting, build in this order and do not skip ahead. Draw the domain map and put a name against every domain. Write the eight attribute publication standard and get it agreed. Take one domain all the way to a published product with a real consumer. Only then generalise the platform and form the governance council. Those first three steps take weeks rather than quarters, they cost attention rather than budget, and they will tell you more about whether your organization can run a mesh than any architecture review will. We are more than happy to help with that first domain, so reach out to Jatin Solanki.
Data mesh architecture arranges analytical data so that the team who already owns a business domain also owns the data that domain produces, publishes it as a product other teams can use without asking permission, and does so on a shared platform that applies one set of governance rules automatically. It is built on four principles: domain oriented ownership, data as a product, a self serve data platform, and federated computational governance.
The useful way to draw a data mesh is as four horizontal planes. At the bottom sit the operational domain systems that run the business, unchanged. Above them sit the domain data products, which are the documented and versioned analytical outputs each domain publishes for everybody else. Underneath both runs a domain agnostic self serve platform providing storage, pipelines, catalog, lineage, monitoring and access control. Around all of it sits a federated governance plane whose rules the platform applies at publish time. The ownership boundary runs vertically: domains own the first two planes and a central platform team owns the other two.
The four principles are domain oriented ownership, which puts each dataset under the business domain that produced it; data as a product, which requires every published dataset to carry an owner, a definition, a stable address, a versioned schema contract, a quality threshold, lineage, an access policy and a support channel; a self serve data platform, which gives domains paved paths so they can publish without central engineering; and federated computational governance, which means a small set of globally agreed rules enforced automatically inside the publication pipeline rather than written in a document.
Implement it in six steps and do not reorder them. First, draw the domain map and name an accountable owner for each domain. Second, agree the publication standard before anything is published. Third, stand up the self serve platform for one pilot domain only. Fourth, publish the first data product and find a real consuming team to depend on it. Fifth, form the governance council and turn each agreed rule into an automated check in the publication pipeline. Sixth, onboard the remaining domains one at a time, measuring how many products meet the standard rather than how many products exist.
The core concepts are the domain, which is a business area that owns its own systems and the data they produce; the data product, which is a domain output published with an owner, a contract and a quality guarantee; the self serve platform, which is the domain agnostic tooling every domain builds on; and federated computational governance, which is the small set of global rules that the platform enforces. A data mesh is those four concepts working together. Any three of them without the fourth is a partial implementation that reverts to a centralized model over time.
The difference is structural rather than technological, and a data mesh often runs on the same warehouse or lake. In a centralized architecture a central data team models the data, owns the pipelines and applies governance, so every new question queues behind that team. In a data mesh the domain that produced the data models and publishes it as a product with a named owner and a stated quality threshold, a central platform team supplies the tooling rather than the pipelines, and governance rules are agreed centrally but applied automatically at publish time.
The engineering team that already runs an application keeps its operational systems. A named data product owner inside the business domain owns each published data product and is accountable to its consumers for the product behaving as documented. A central data platform team owns the self serve tooling and is measured on how widely its paved paths are adopted. A federated governance council made up of domain representatives plus the platform team, security and legal owns the global rules, and the platform team is responsible for turning each rule into a check that runs.
No, and the two are unrelated. A mesh data center refers to a physical network topology in which infrastructure nodes are connected to each other by many paths, so traffic can route around a failure. A data mesh is an approach to organizing analytical data and the teams who own it, and it is not a networking arrangement at all. If you are researching network resilience rather than data ownership, this article is not the one you want.

First step to AI Readiness
Table of Contents
Sneak peek from the data world.


Bring lineage, quality, governance, and AI together in one platform—so your teams and AI agents can act with confidence.